AI-assisted human agents are people who use AI suggestions while remaining responsible for completing a task. Assess their teamwork by comparing final outcomes with a human-only baseline, adding an AI-only benchmark where safe, and counting review work and consequential mistakes alongside speed. Start with one defined task and a fair set of cases before making a rollout decision.
What would count as a better human-AI team?
A better team produces a useful improvement under the conditions that matter to the business. That might mean more correctly resolved requests per hour, fewer important omissions, or the same quality with less effort. A fluent draft, a high acceptance rate and an enthusiastic demo are observations about the interaction; none establishes that the completed work improved.
Define the outcome at the point where the customer or next worker receives it. For a support agent, that might be a correct resolution that does not reopen within a specified follow-up window. For a document-review assistant, it might be a required fact found and verified against the original. Keep consequential errors separate so that excellent tone cannot cancel an unauthorized action.
Use the human-only condition to answer whether assistance helps people. Use an offline AI-only condition to ask whether the combined system adds quality beyond its stronger component. AI-only benchmarking is not permission to let software act without oversight; some tasks must remain simulated or restricted regardless of benchmark performance.
The distinction matters because collaboration is not automatically beneficial. A meta-analysis of 106 experiments found that human-AI combinations, on average, underperformed the better of the two working alone, with substantial variation across tasks. Its experiments were published between January 2020 and June 2023, so it provides a reason to test complementarity rather than a forecast for every current product.
Treat the proposed evaluation as a test of a particular workflow: people, model, information sources, interface, permissions and task mix. A model can answer a question correctly while its surrounding process loses an important detail or encourages an unjustified override. If you still need to choose the service workflow itself, the separate AI customer-service setup guide owns that broader implementation decision.
Before running cases, agree on the following acceptance conditions with the person responsible for the operation. These are local decision rules, not universal industry thresholds. Fix them before seeing results so that the team cannot redefine success around whichever number happens to improve.
- Primary outcome: one observable definition of acceptable completed work, applied to every condition.
- Safety boundary: which errors require a pause or restriction, even when the average score improves.
- Efficiency boundary: what review, repair, waiting and repeat-contact work belongs in the comparison.
- Evidence boundary: which people and case types the pilot actually represents, and what remains untested.
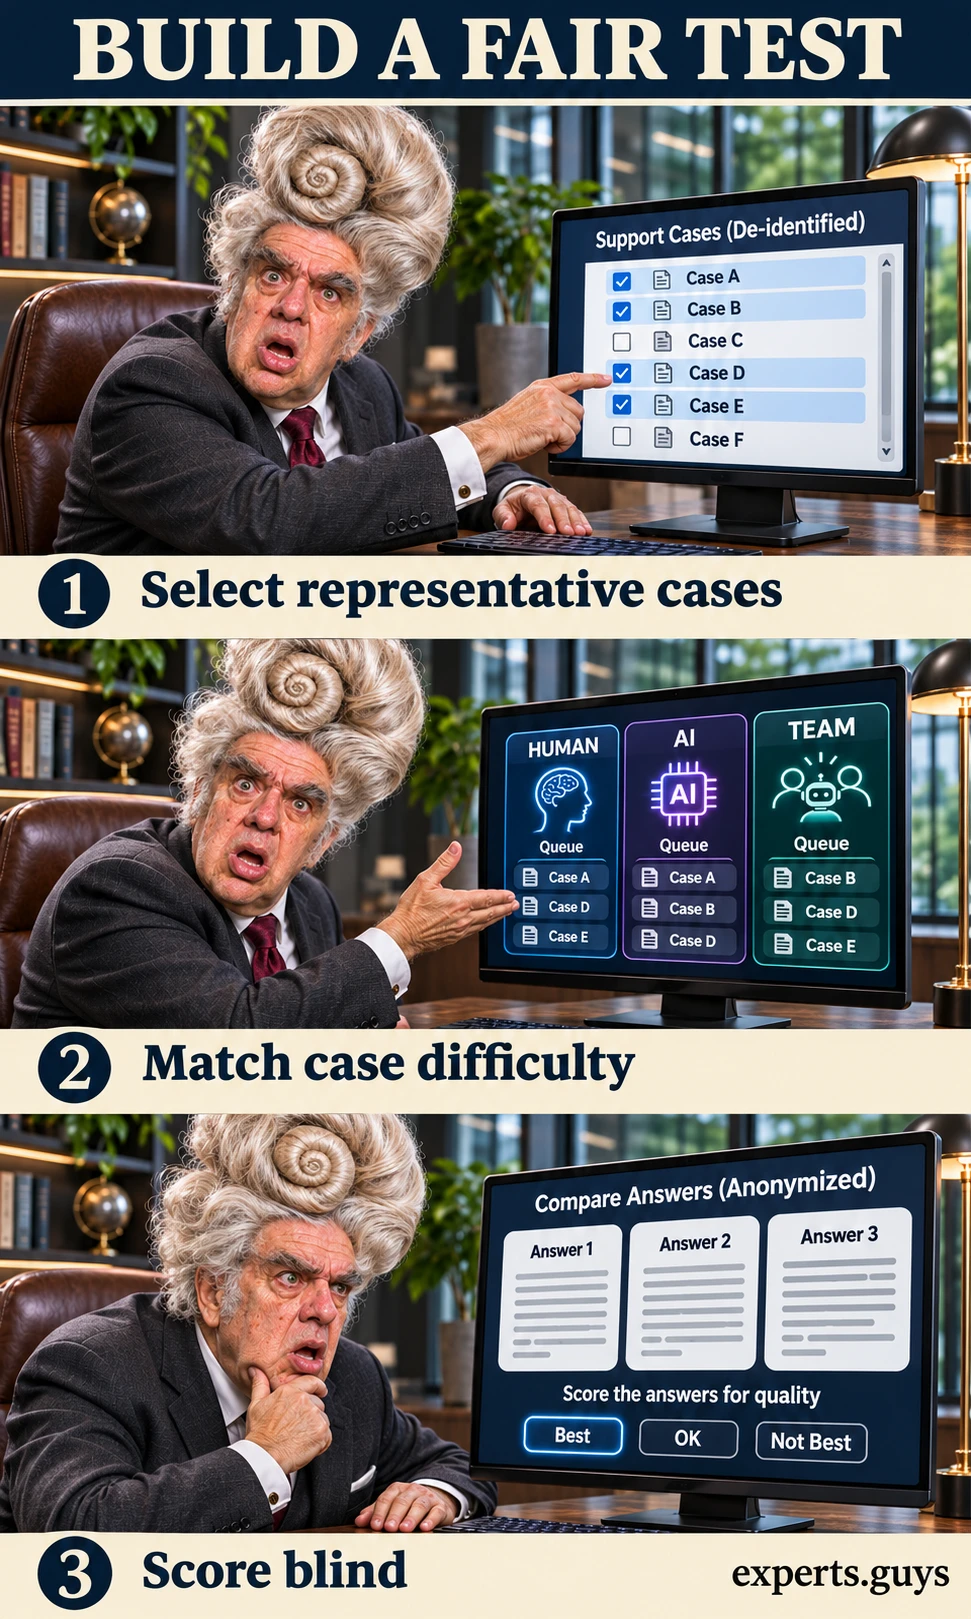
1. Build a fair comparison before testing the assistant
Use this procedure when a demo or before-and-after report makes the assistant look promising but does not isolate its effect. Prepare a de-identified set of representative tasks, their source material, and a scoring rubric. Keep confidential customer information inside approved systems; evaluators generally need the relevant facts, not names, account identifiers or unnecessary conversation history.
Select routine cases, exceptions and ambiguous cases in proportions that resemble the intended workload, while keeping a separately labelled stress-test set for rare consequential failures. Do not mix deliberately difficult challenge cases into a production-rate estimate without explaining the different sampling. Keep test cases separate from examples used to tune prompts or train staff.
Assign comparable cases to the human-only and assisted conditions using random allocation where feasible. Balance agent experience and case difficulty. Avoid giving the same person an identical case twice: remembering the answer can look like an AI benefit. A crossover design can use different matched cases and vary condition order, but it still needs attention to learning and carryover.
Run the AI-only benchmark on the same task definition in a sandbox, with equivalent source access and allowed tools. Remove condition labels before a separate evaluator scores the final output. For judgment-heavy tasks, have two evaluators independently score a subset, resolve disagreements, and clarify the rubric before treating small score differences as meaningful.
A manageable rehearsal can use a small batch to expose broken instructions, missing fields and scoring disagreement. It cannot establish a precise improvement rate or rule out rare harm. If staffing is limited, begin with a historical replay and label it as a replay; the completion checkpoint is a reproducible test setup, not a claim that a few successful cases validate deployment.
Which metrics should you measure?
Use a small set of metrics with different jobs. Quality answers whether the work is correct, efficiency answers what it takes to complete it, and guardrails answer what must not happen. Keeping these dimensions visible is more informative than collapsing them into a weighted score whose weights nobody can explain.
For a binary quality outcome, acceptable cases divided by evaluated cases gives a pass rate. If the team passes 92 of 100 cases and the human-only condition passes 84 of 100, the observed difference is 8 percentage points. That is not an 8 percent relative improvement; the relative change is about 9.5 percent, and neither expression tells you whether the difference is statistically reliable.
If the offline AI-only pass rate is 90 percent, the same team has an observed 2-percentage-point advantage over the stronger solo condition. This is a descriptive complementarity gap. A small positive gap does not establish synergy without adequate sampling and a suitable analysis, and an unavailable AI-only benchmark means that particular comparison cannot be made.
Choose the scoring unit before counting: one customer issue, one document, or one decision. Multiple turns inside the same issue are usually correlated, as are multiple cases handled by the same agent. Treating every turn as an independent observation can make evidence appear more precise than it is.
The following scorecard keeps the denominators explicit. Define the follow-up window, severity rubric and handling-time boundaries once, then use them consistently across conditions. Preserve counts alongside percentages so that a perfect result from a tiny sample remains visibly different from a broad evaluation.
| Measure | Calculation or observation | What it tells you |
|---|---|---|
| Final quality | Acceptable completed cases / all evaluated cases | Whether the end result meets the fixed rubric. |
| Critical errors | Count and rate, grouped by severity | Which failures cannot be averaged away. |
| Total handling effort | Human minutes across handling, review, repair and follow-up | Whether generation speed becomes useful capacity. |
| Harmful acceptance | Incorrect AI advice accepted / incorrect AI advice shown | Whether oversight catches bad suggestions. |
| Harmful override | Correct AI advice changed into an incorrect final choice / correct advice shown | Whether intervention damages a correct recommendation. |
| Recovery | Successful handoffs and unresolved cases under failure | Whether work can continue when assistance fails. |
2. Check the source before reading the draft
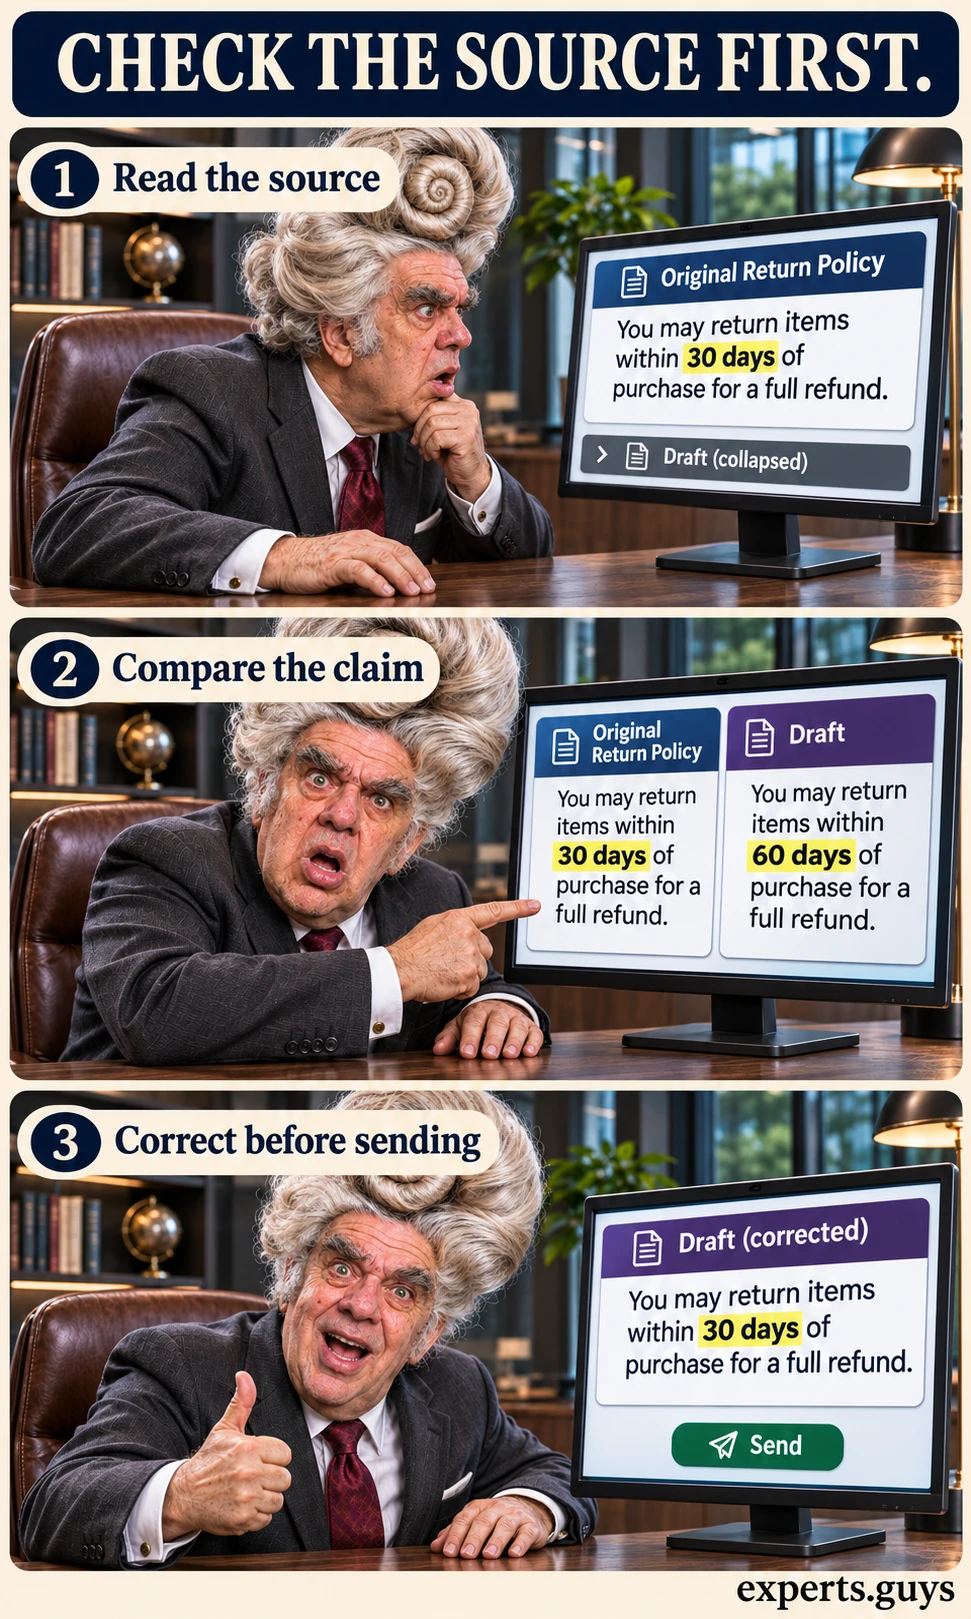
Use a source-first check when plausible wording can anchor the reviewer. Prepare a sandbox case with an authoritative source and a draft containing a specific mismatch. Begin by opening the source with the draft hidden or collapsed. Identify the rule that controls the answer, then reveal the draft and compare the relevant claim directly with that rule.
- Open the source: confirm that the policy or record applies to this case and is the intended version.
- Reveal the draft: compare the decisive claim, including units, dates, exceptions and eligibility conditions.
- Correct or withhold: repair the unsupported claim, or escalate when the source does not resolve the question. Recheck the final answer before sending.
In the fictional visual example, the source gives a 30-day return window and the draft says 60 days. The successful action is to identify and correct that mismatch. The evaluator should also check whether the agent notices an exception or missing purchase date rather than copying “30 days” mechanically into every response.
A common mistake is verifying only that a citation opens. A real page can still fail to support the sentence attached to it. If full documents are cumbersome, provide a relevant source passage plus access to the complete version; do not substitute another summary whose correctness has not been checked. Score both the error caught and the final answer, including cases where the reviewer introduces a new error.
3. Test whether acceptance and overrides are justified
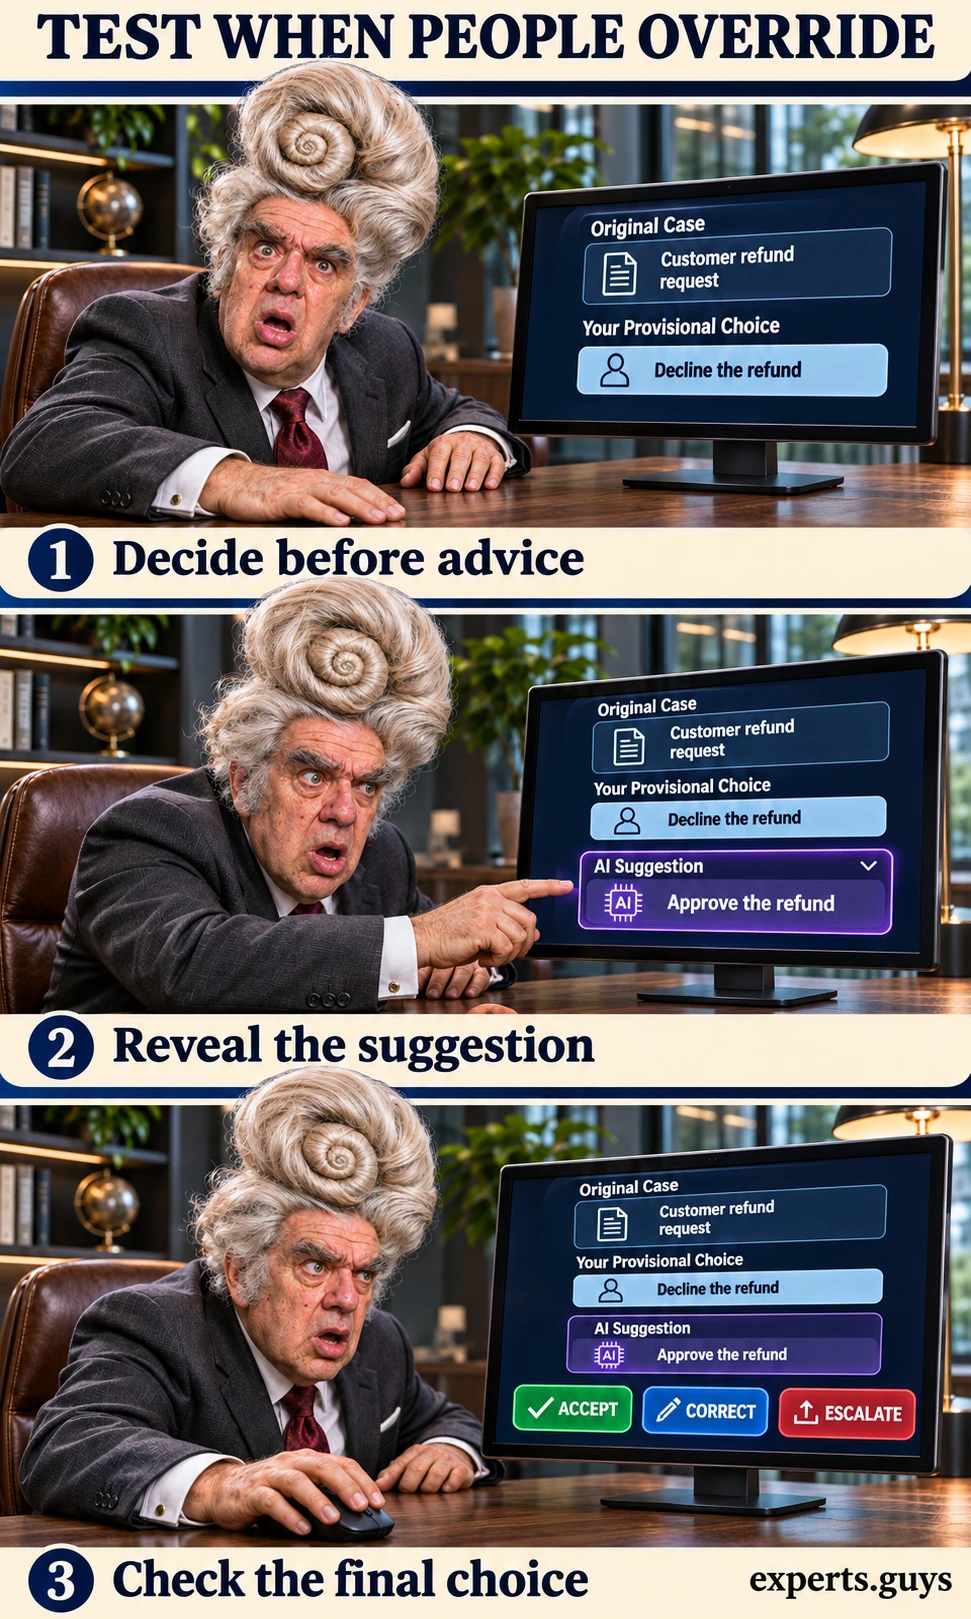
Use a provisional-choice test to understand how advice changes a person’s decision. In a sandbox, let the agent inspect the original case and choose an initial answer before revealing the suggestion. Capture the initial choice through the evaluation interface, then show the advice and capture the final action. The purpose is to distinguish a useful correction from a correct human answer displaced by bad advice.
- Prepare mixed advice: include correct, incorrect and genuinely ambiguous suggestions with independently checked answers.
- Reveal after an initial choice: preserve the initial and final selections automatically, without asking agents to keep a separate written diary.
- Classify the transition: inspect helpful acceptance, harmful acceptance, helpful correction and harmful override against the rubric.
Suppose a person initially recognizes that an exception needs approval, but follows a confident suggestion to resolve it immediately. Agreement increased while control weakened. Conversely, an agent who rejects a correct suggestion for an unsupported reason has not demonstrated good judgment simply by exercising an override. The separate explanation of AI trust and uncertainty provides background; this test measures the resulting behavior.
Keep the denominator tied to advice quality. If 12 of 20 incorrect suggestions are accepted, harmful acceptance is 60 percent of incorrect suggestions, not 12 percent of a larger 100-case set. If there are no incorrect suggestions, that rate is unmeasured, not zero. Constructed error cases reveal vulnerability but do not estimate how often the live assistant makes those errors.
An initial-choice step adds work and can change behavior, so use it as a diagnostic condition rather than quietly inserting it into the normal productivity estimate. A lighter alternative is replaying selected decisions with the agent and asking which evidence changed the action. That gives qualitative insight but cannot reconstruct an uncaptured initial judgment with certainty.
4. Count review and rework across the whole job
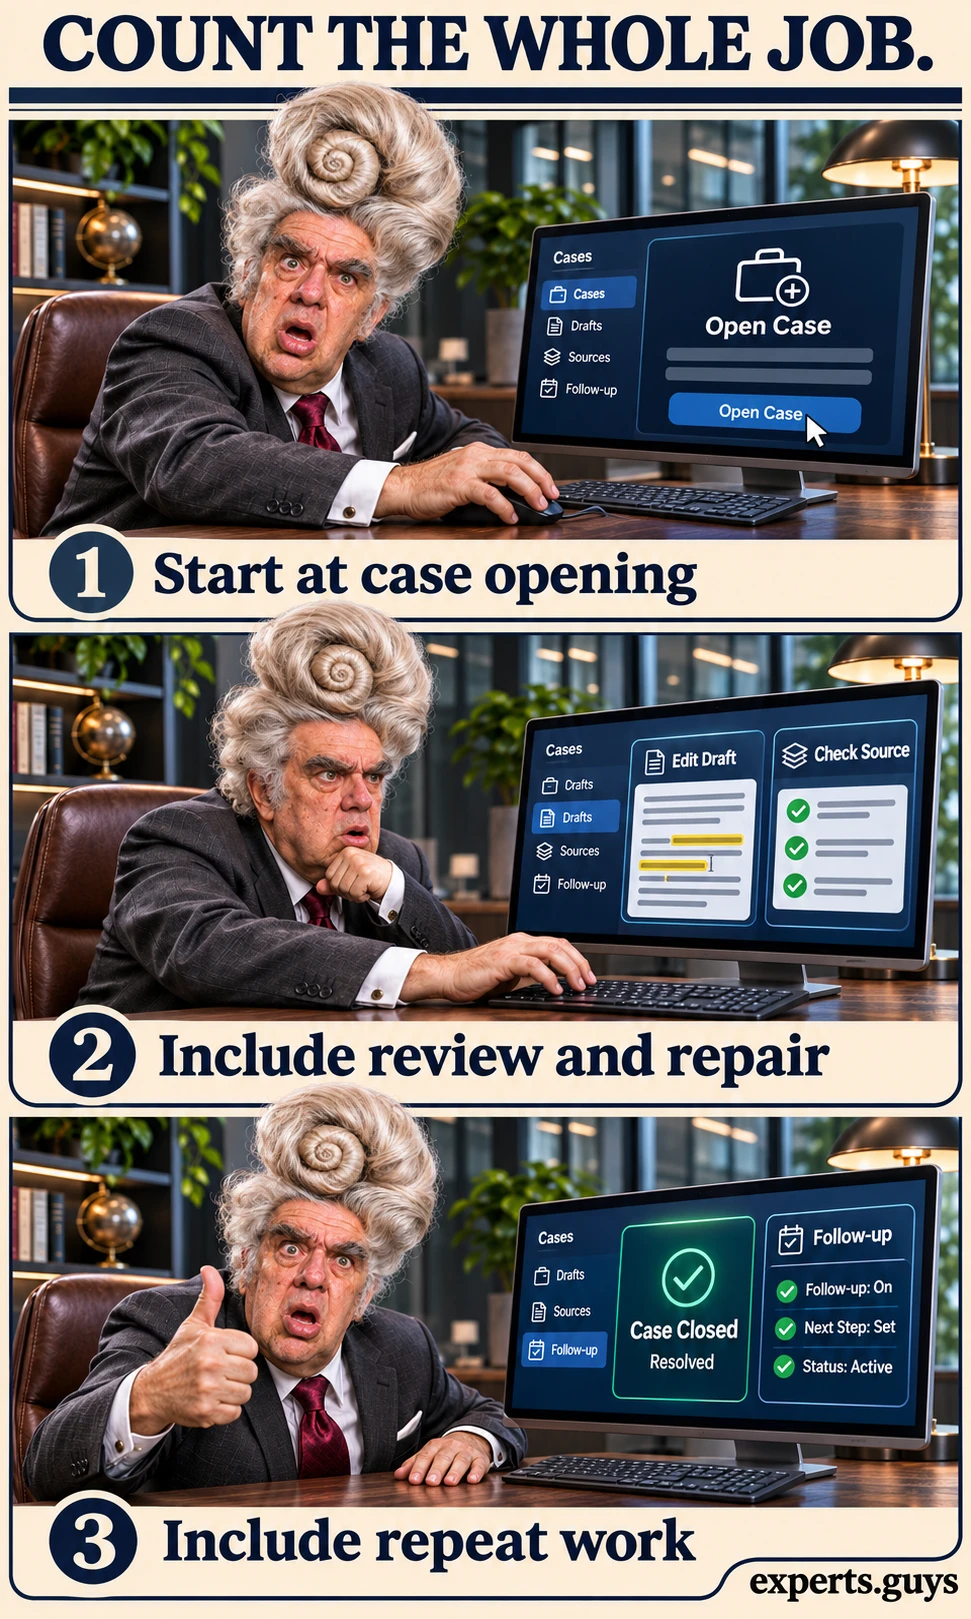
Use this method when drafting time falls but the team still feels overloaded. Define a start event, an acceptable completion event and a fixed follow-up window. Obtain timestamps and work durations from the approved case system where available. Separate elapsed customer waiting time from human handling effort, especially when agents manage simultaneous conversations.
- Start consistently: include the same handling stages in both conditions.
- Include repair: count source checking, rewriting, supervisor intervention and follow-up effort once each.
- Inspect the tail: compare typical cases and slow exceptions, while reporting unresolved work separately.
Consider an illustrative workload where the human-only condition requires 12 minutes per case. The assisted condition uses 5 minutes for initial handling, 3 for checking and 2 for correction and follow-up, for a total of 10 minutes. The observed saving is 2 minutes, or about 16.7 percent. If later repeat work adds another 3 minutes, the apparent saving becomes a 1-minute loss.
Do not sum overlapping wall-clock intervals and call the result labor time. Equally, do not exclude stalled or abandoned cases because they have no completion timestamp. Report their number and current status, and use a consistent accounting rule. When detailed instrumentation is unavailable, an observed sample of complete sessions is a practical first check; describe its coverage rather than projecting it across the entire operation.
Quality-adjusted throughput can be useful: acceptable completions divided by human handling hours. It is a workload measure, not a promise of equivalent cash savings. Licences, integration, supervision, training and incident response still affect cost. Broader workflow fragmentation belongs in why AI productivity gains disappear; this procedure isolates the evaluation boundary.
5. Rehearse a failed handoff in a sandbox
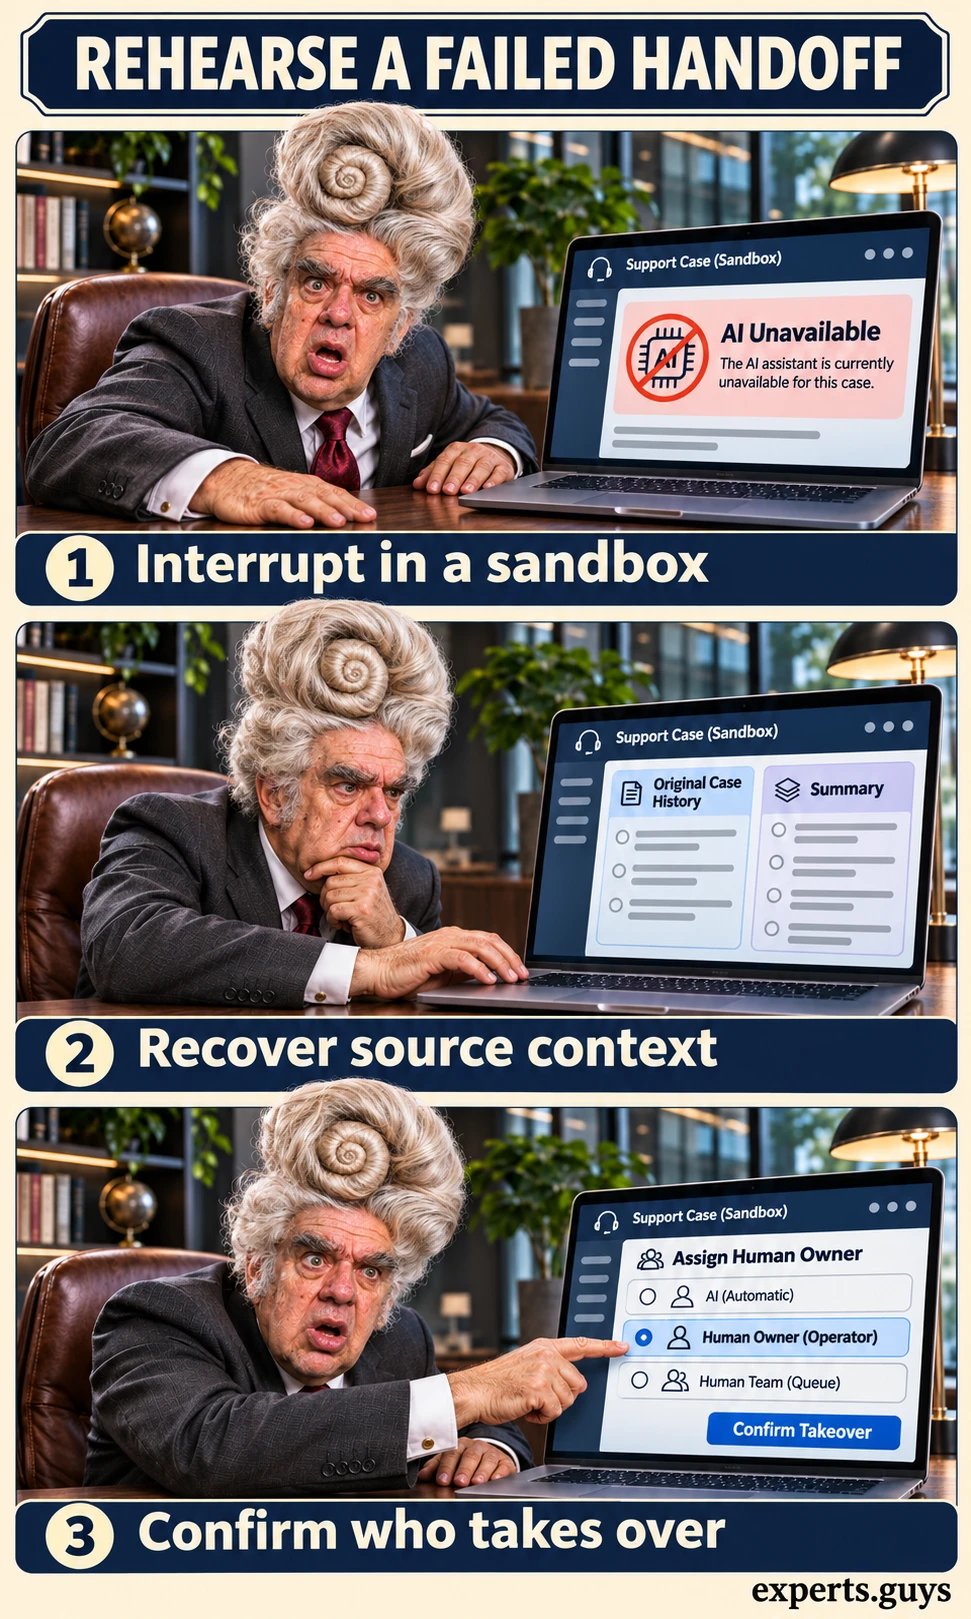
Use a handoff rehearsal before relying on an assistant to transfer context between people or systems. Prepare a simulated case with a known status, relevant source history and a designated receiving role. Introduce one controlled failure, such as an unavailable assistant or a missing source. Keep the test isolated from customer-facing actions and real transactions.
- Interrupt assistance: check whether the agent notices the limitation instead of continuing on a stale suggestion.
- Recover context: open the original case and verify the summary’s decisive facts and unfinished actions.
- Transfer ownership: route to the receiving role and confirm that a human can resume without repeating an already completed action.
The checkpoint is continuity: the receiving person can explain what is known, what is unresolved and what action is permitted next. A “transferred” badge is insufficient if no one owns the queue. A concise recap from the recipient can expose an omitted exception much faster than asking whether the summary looked clear.
Do not combine an outage, misleading source, permission failure and overloaded queue into the first test. A single controlled change makes the cause easier to identify. If a dedicated sandbox is unavailable, use a tabletop replay with disabled action controls and acknowledge that it tests procedure rather than the actual integration. Pause expansion when staff cannot recover original evidence or identify the next owner.
6. Check who benefits and which cases deteriorate
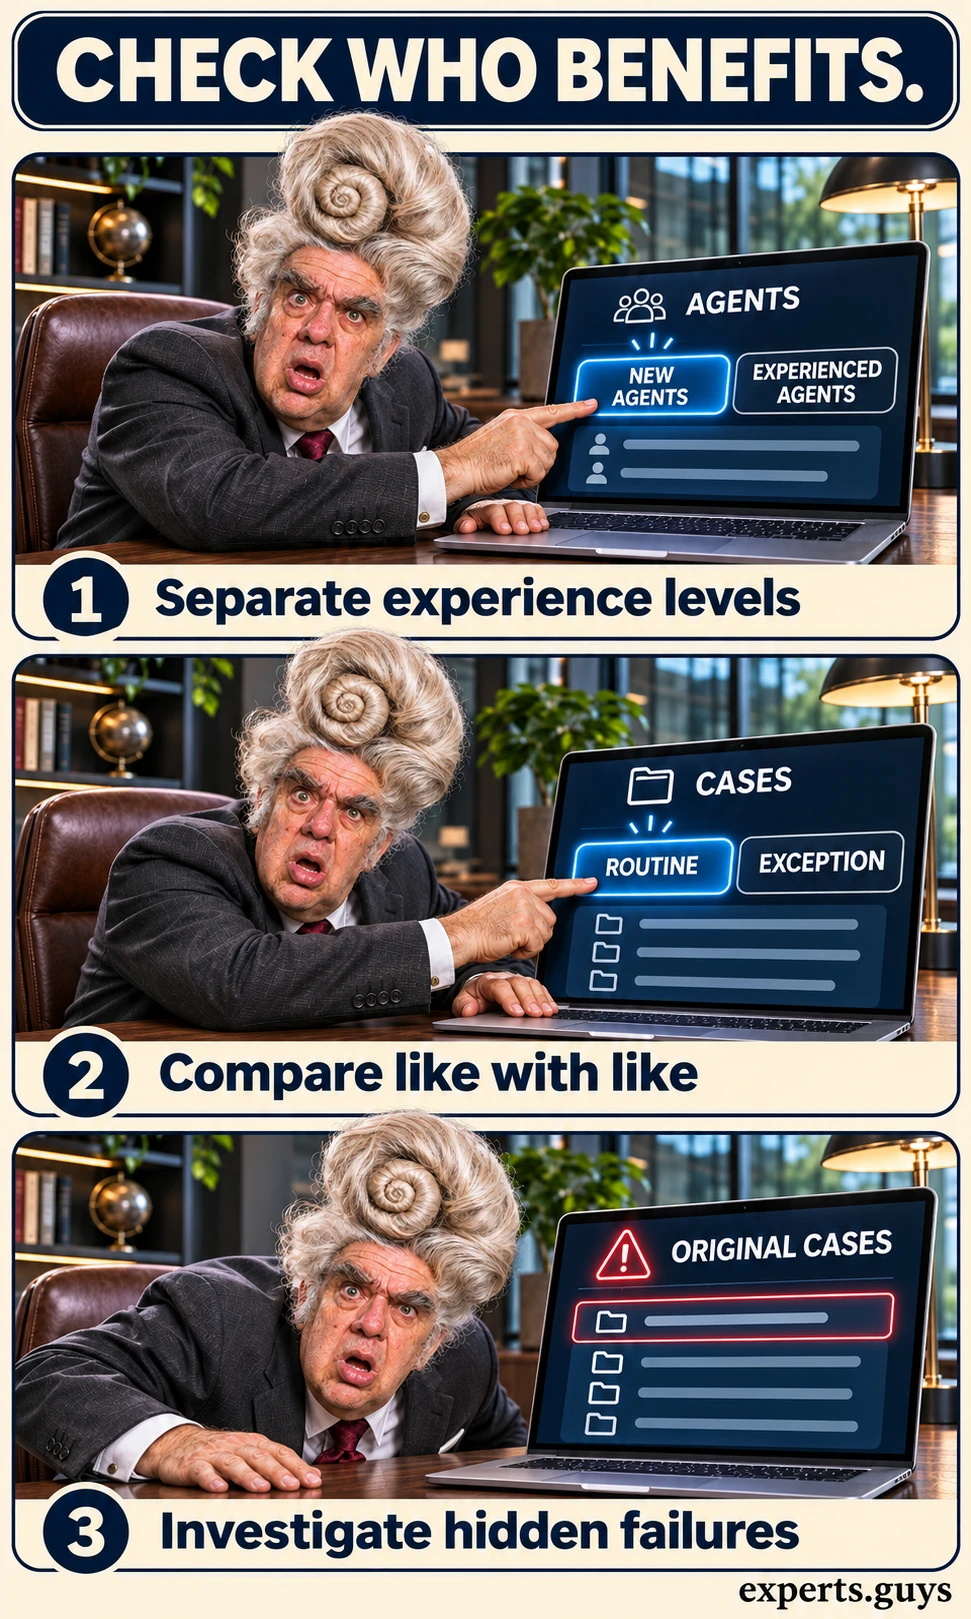
Use subgroup inspection when an overall average looks positive. Separate results by preselected factors that change the work, such as agent experience, task difficulty, language or escalation need. Compare equivalent case mixes within each group and retain the group sample sizes. Do not treat tiny slices as firm rankings of employees or customer populations.
The published Generative AI at Work study examined 5,172 customer-support agents and reported an average 15 percent increase in issues resolved per hour. Benefits varied across workers; the most experienced and highest-skilled agents had small speed gains alongside small quality declines. This was one workplace setting and system, not a target every deployment should reproduce.
- Separate experience levels: check whether newer and experienced agents have different quality and effort changes.
- Separate case types: distinguish routine requests from exceptions before comparing results.
- Inspect failures: reopen the underlying cases behind a negative pattern and test a specific explanation.
For example, assistance might speed up routine replies while making unusual requests harder to resolve because staff spend time undoing an unsuitable draft. A useful response is to restrict the assistant on that case type and repeat the relevant comparison. Automatically giving everyone more training would be a weak correction if the source retrieval is the actual failure.
If there are too few observations, merge only categories that are operationally comparable or collect more cases. Do not repeatedly search dozens of slices until one appears significant. Plan the important comparisons in advance and label later discoveries as exploratory. A successful subgroup check produces a narrower, better-supported usage boundary, not a league table.
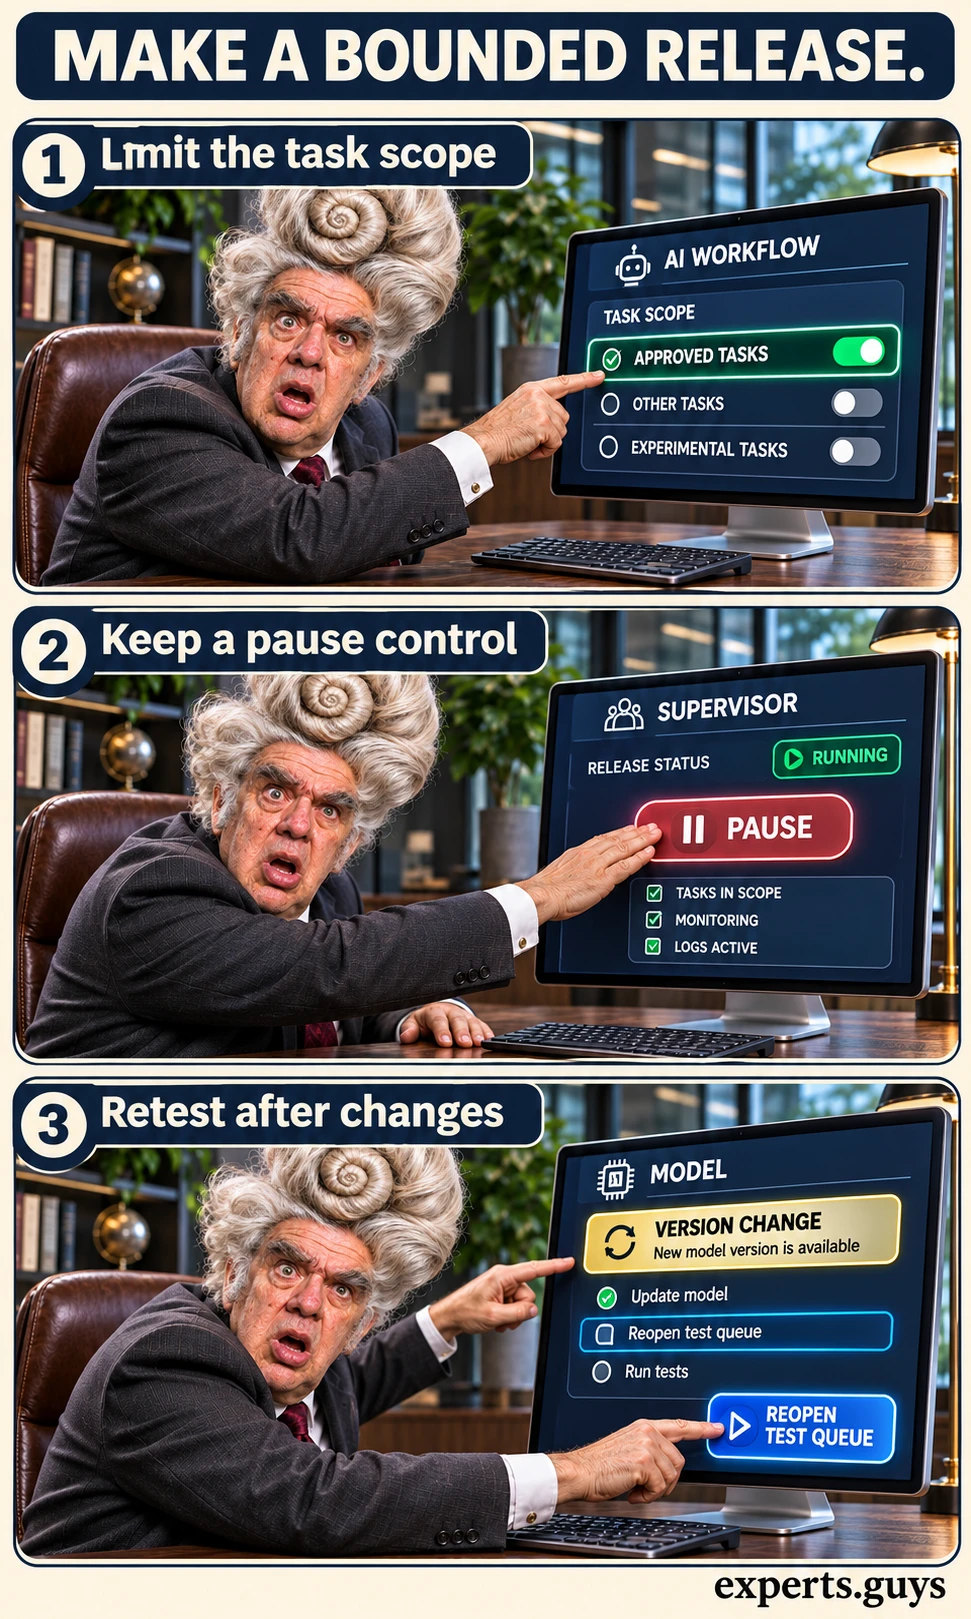
7. Make a bounded release decision and retest changes
Use a staged decision after the quality, reliance, time and recovery checks. Compare results with the acceptance conditions chosen at the start. Keep a critical-error review separate from the ordinary pass-rate comparison. A serious failure may warrant restricting a workflow even when its estimated frequency is uncertain.
- Limit the release: enable only the tested tasks, information sources and permissions.
- Keep control: assign a person who can pause the workflow and confirm that the fallback works.
- Retest relevant changes: reopen the evaluation after material changes to the model, prompt, retrieval source, interface or permitted actions.
A practical decision has three possible directions: continue a controlled pilot, narrow and repair the workflow, or pause the affected use. None requires pretending that an aggregate score certifies safety. The NIST AI RMF Measure guidance supports context-sensitive evaluation and measurement of oversight, overrides and reported errors; it does not supply a universal pass percentage for your operation.
| Observed pattern | Reasonable next decision | Evidence still needed |
|---|---|---|
| Quality improves; effort falls; guardrails hold | Continue a bounded pilot | Representative coverage, uncertainty and ongoing monitoring. |
| Speed improves; critical errors appear | Restrict or pause the affected workflow | Root cause, effective correction and a repeat test. |
| Average improves; an important group deteriorates | Narrow the eligible tasks or users | A matched comparison for the affected group. |
| Results are mixed or the sample is small | Keep the conclusion provisional | Additional independent cases and clearer scoring. |
Avoid changing the rubric halfway through a run and then merging the scores. Version the test definition alongside the system configuration so that later results remain interpretable. A smaller team can keep one approved configuration and a repeatable set of historical cases; it still needs fresh cases to detect overfitting to that set. Completion means a named owner has a defensible scope and a working pause route.
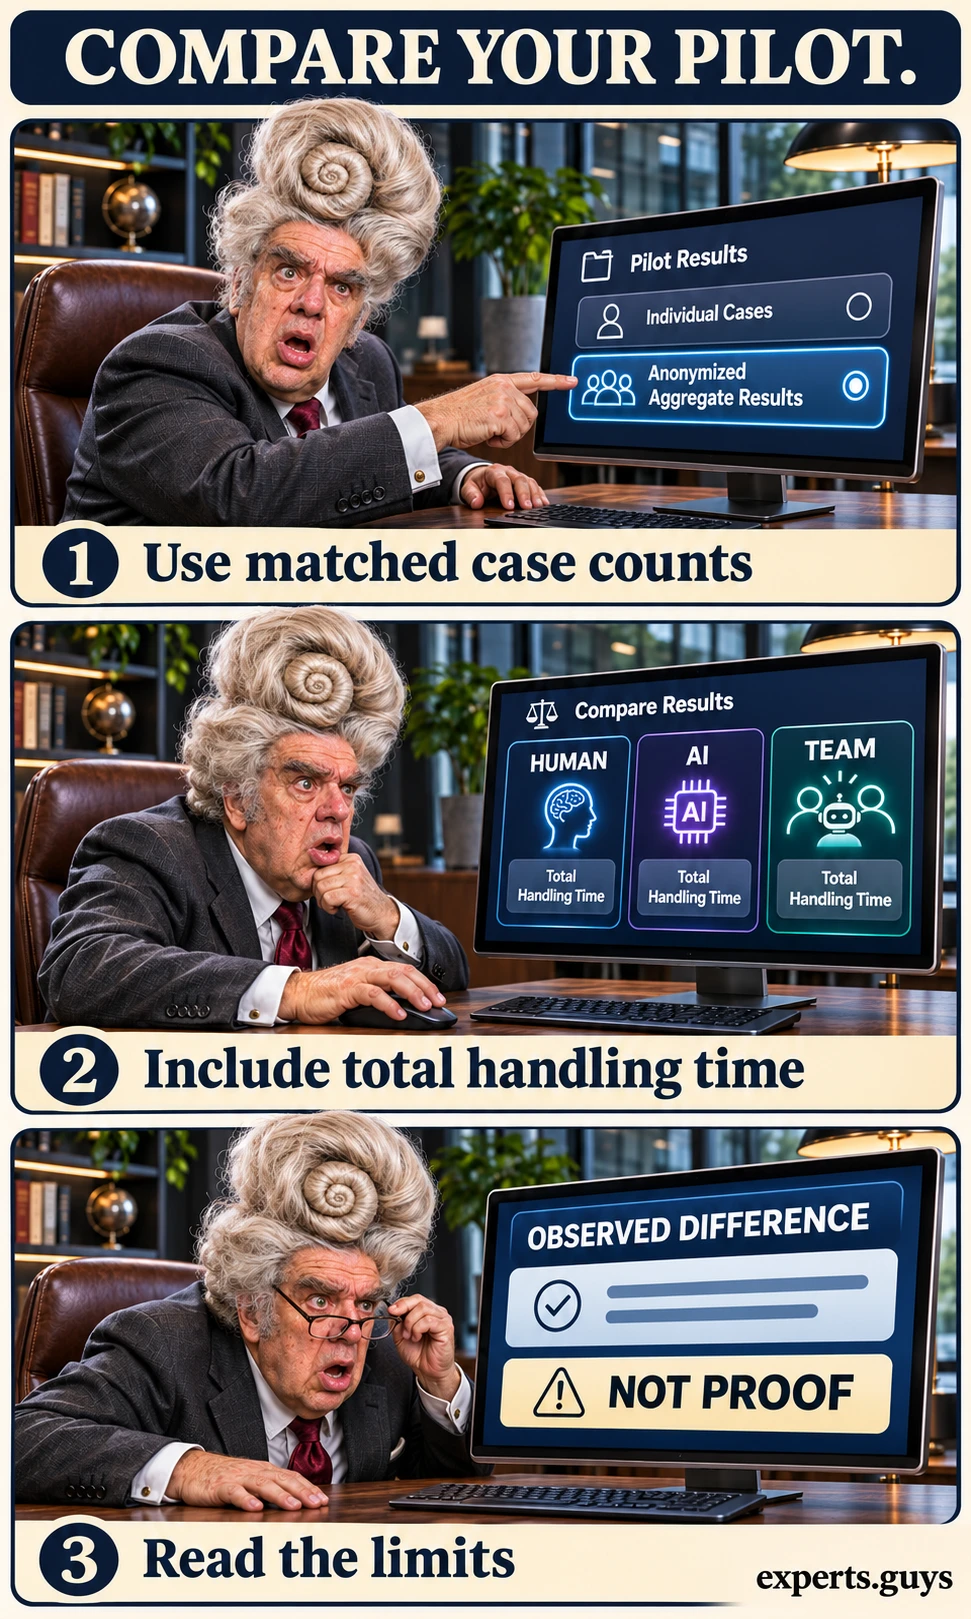
8. Compare your pilot with Team Evidence Check
Team Evidence Check calculates descriptive quality differences and handling-time changes from aggregate results. It helps you see whether the team exceeds the human-only condition and, when available, the stronger solo benchmark. It does not calculate statistical significance, evaluate the representativeness of your sample or approve a release.
- Enter counts: use evaluated and acceptable cases from the same task definition and comparable case mix. Leave the AI-only benchmark disabled if it was not measured.
- Enter total human minutes per case: include review and follow-up under the same boundary in both conditions. Add the team’s critical-error count.
- Read the result and limits: use the arithmetic to select the next evaluation step, then open the optional A4 action card for the assumptions and counts.
The built-in example is fictional: 84 of 100 human-only cases, 90 of 100 AI-only cases and 92 of 100 team cases pass, with 12 versus 10 human minutes per case. Its 8-point human comparison, 2-point stronger-solo comparison and 16.7 percent time reduction illustrate the formulas. Replace those values with your own aggregate evidence; do not enter customer records, names or case text.
Team Evidence Check
See what your pilot actually shows.
Compare final quality and total handling time. Keep the limits visible before expanding access.
Fictional example loaded. Replace it with aggregate results from comparable cases. Inputs stay in this page; no customer records are needed.
JavaScript is required for calculation. The article explains the manual formulas.
This comparison is descriptive. It does not measure statistical significance, certify safety or approve deployment. Counts alone cannot control for repeated agents or selection bias.
How much evidence is enough?
There is no universal case count that makes a human-AI assessment reliable. The required sample depends on the baseline error rate, the smallest worthwhile improvement, variability across people and cases, and the consequences of missing a failure. A small operational rehearsal can find obvious defects; estimating a modest improvement or a rare serious error usually requires much more evidence.
For a larger decision, preserve case-level results and the assignment design so an appropriate analysis can account for repeated agents, matched cases and subgroup comparisons. Aggregate pass counts alone cannot recover those relationships. Confidence intervals, when used, should match the design rather than treating correlated observations as independent.
Do not interpret “no critical errors observed” as “no critical risk.” Rare conditions might be absent from the sample, and deliberate challenge cases answer a different question from randomly sampled traffic. Keep both kinds of evidence: representative cases for expected operation, stress cases for known failure boundaries, and a clear explanation of what each can support.
Frequently asked questions
Can an AI judge score the evaluation?
It can help triage outputs or apply a preliminary rubric, but its judgments need validation against independent human scoring for the actual task. Check disagreements and consequential cases. Using the same system to produce and approve its own answers can conceal shared errors.
What if an AI-only test is impossible?
Compare assisted work with a valid human-only baseline and report the AI-only benchmark as unavailable. You can estimate the observed benefit of assistance, but cannot claim the combined team beats the stronger solo component without that missing comparison.
Should customer satisfaction be the main metric?
It can be a useful outcome, but a friendly response may still be incorrect or create repeat work. Pair satisfaction with final resolution quality, consequential errors and follow-up. Keep survey response rates visible because the people who reply may differ from those who do not.
Does a high override rate mean the assistant is poor?
Not by itself. Overrides may correct bad advice, damage correct advice, or reflect cases the assistant should never handle. Inspect whether the original advice and the final answer were correct before interpreting the rate.
Can these methods approve legal or medical use?
No. The general evaluation approach can organize evidence, but it does not replace domain-specific validation, professional responsibilities or applicable requirements. Keep consequential actions restricted to the scope and oversight established for that use.
Can the calculator determine statistical significance?
No. It displays arithmetic differences from the aggregate values you enter. It does not model repeated agents, paired cases, case mix, selection bias or uncertainty. Use the original evaluation design and case-level data for an inferential analysis.
Your next step
Choose one task, freeze its acceptance rule and run a de-identified comparison that preserves both final quality and total handling effort. Then inspect the disagreements and failed handoffs before expanding access. The most useful assessment tells you exactly where the team helps, where it needs repair and what evidence is still missing.