A chatbot is software that carries on a message exchange; four useful types are rule-based, intent-based, generative and hybrid chatbots. They differ in how they select a response, so choosing between them starts with the conversation you need to support rather than an assumed ladder of intelligence.
These four categories are a practical comparison framework, not an official standard or an exhaustive inventory. Products often combine them, and terms such as voice, contextual, transactional and AI-powered describe overlapping characteristics. The useful question is what happens between the customer’s message and the answer on screen.
Which four chatbot types are useful to compare?
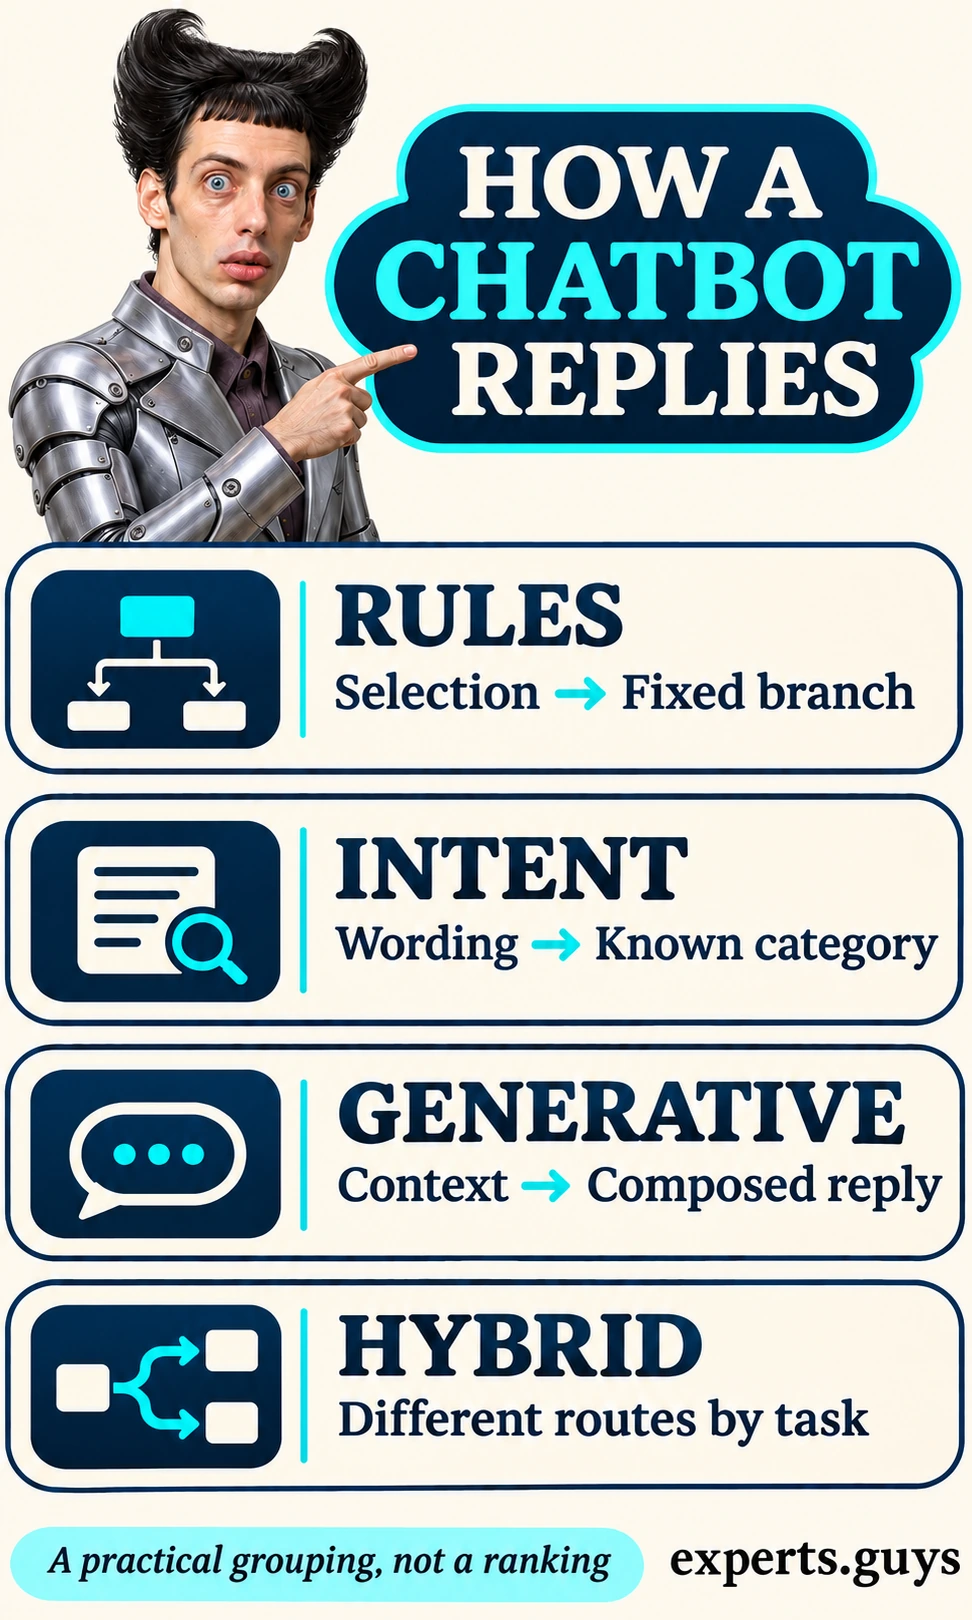
Compare the response mechanism first. A rule-based bot follows defined branches; an intent-based bot maps wording to a known purpose; a generative bot composes language; a hybrid combines approaches within one experience. A vendor’s product name may tell you much less than the configuration of the particular conversation you are buying.
For a small set of clear choices, explicit branches can be enough. When people describe the same need in many ways, intent recognition can remove menu navigation without surrendering control of the final wording. When explaining varied source material is the main job, generation becomes relevant; when the jobs differ within a conversation, combining approaches can make sense.
Think of the distinction as a division of work. Someone or something interprets the input, chooses a route, obtains any required information, and delivers a response. Those stages can use different technologies. A language model at the first stage does not require generated wording at the last stage, and a scripted reply can contain a value returned from a live system.
| Type | What selects the response | Useful fit | Main trade-off |
|---|---|---|---|
| Rule-based | A defined condition or branch. | Finite choices and approved wording. | Coverage must be designed explicitly. |
| Intent-based | A recognized purpose and required details. | Varied wording for known tasks. | Nearby intents and missing details can be confused. |
| Generative | A language model composes the reply from available context. | Flexible explanations and source-based synthesis. | Plausible wording can exceed the evidence. |
| Hybrid | Different mechanisms handle different parts of the exchange. | Mixed explanation, workflow and exception needs. | Route switches and shared state need coordination. |
Swipe horizontally to compare on narrow screens.
1. Rule-based chatbots: defined choices and branches
A rule-based chatbot selects its next step using conditions that a designer has specified. Buttons, menus, keyword matches and structured answers can all supply those conditions. The key property is an explicit path: given the same relevant state and input, the configured rule selects the corresponding branch. A button is an interface choice, not the definition of the entire architecture.
Consider an illustrative store menu with Returns and Delivery. Choosing Returns opens an item-condition question; choosing Unopened then displays the relevant approved response. The bot does not need to infer what the customer meant by a long complaint. It needs the choices to be understandable, the branches to cover the intended cases, and the text at each destination to remain correct.
The attraction is inspectability. An editor can open the branch for an opened item and see the wording customers receive. If the business changes a rule, the affected branch can be identified directly. This makes a small, stable set of routes relatively easy to reason about. It does not prove that every branch is complete, accessible or connected to the right information.
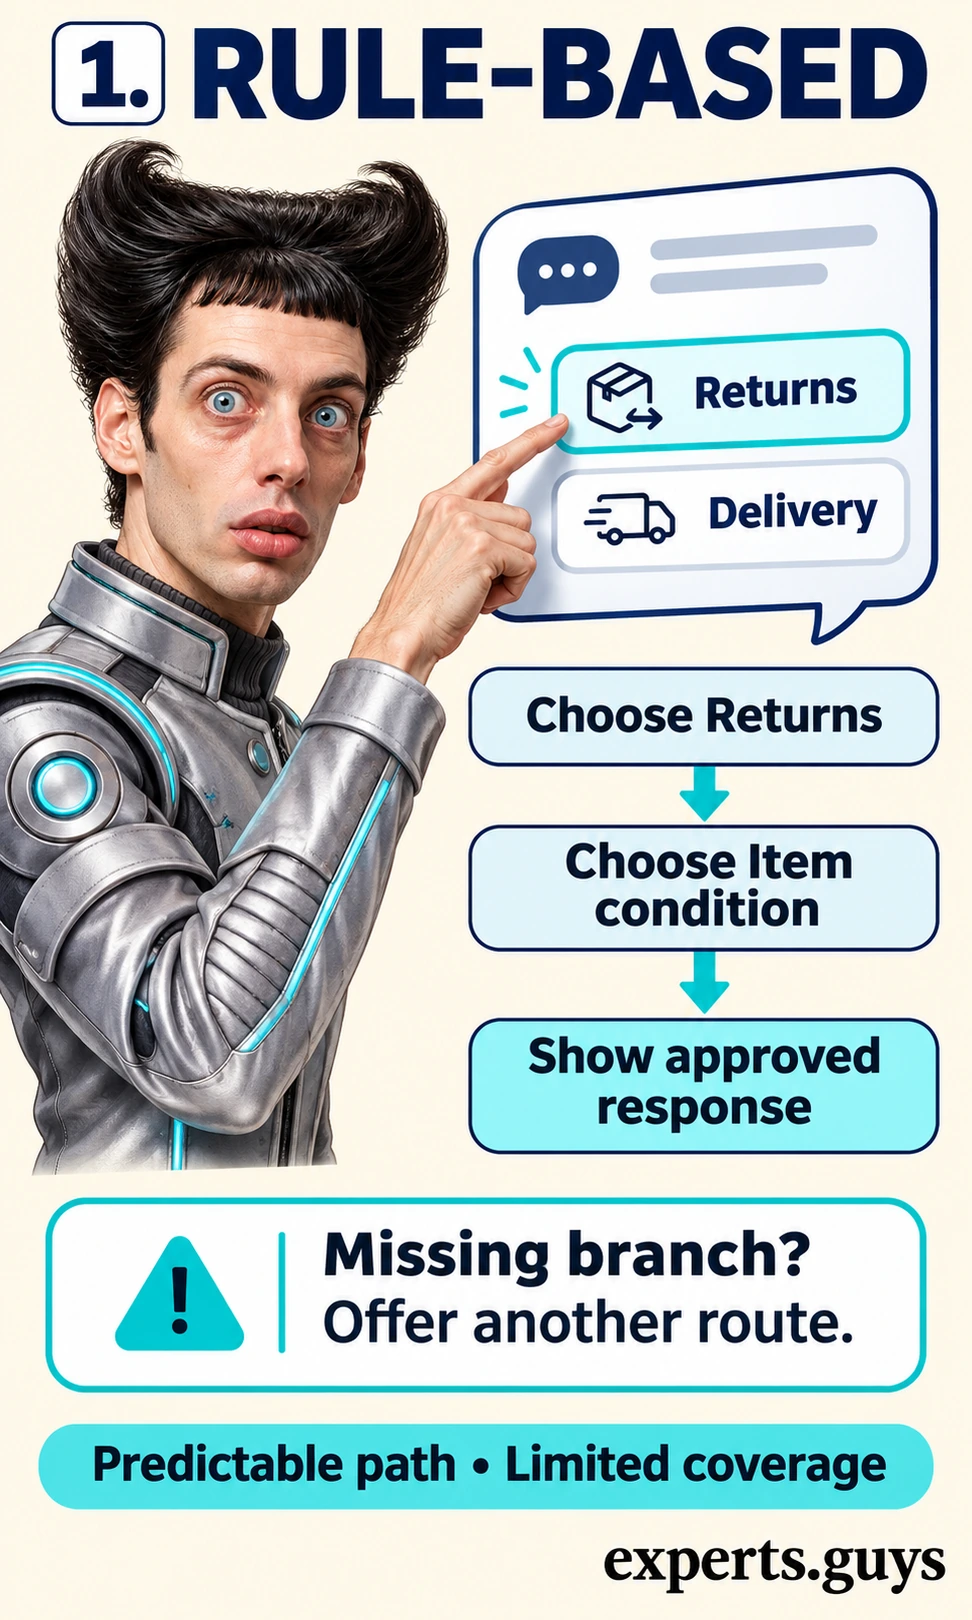
Rules become awkward when the menu expands faster than users can navigate it. A returns conversation may need to distinguish product condition, purchase channel, delivery issue and reason for contact. If those distinctions are presented in the wrong order, a customer can take several correct-looking steps and still arrive at an irrelevant response. The limitation is often the design of the choices rather than a lack of conversational personality.
- Choice coverage: the supported customer condition has a visible destination.
- Recovery: a wrong selection can be corrected without restarting the entire conversation.
- Exit: an unsupported condition has an honest alternative rather than an irrelevant answer.
Keyword rules deserve particular care. The word cancel appears in both Cancel my order and Do not cancel my order. A simplistic match can treat them alike. Adding more keywords may create conflicting rules instead of solving the ambiguity. For a narrow menu, a clear choice can be safer than pretending that a text field understands every sentence entered into it.
A rule-based bot can still use a backend connection. A selected store location might retrieve opening hours from a maintained database, for example. That does not turn its routing into generative reasoning. It also means the bot is only as current as the data connection and the value it receives. A fixed sentence around an incorrect database value remains an incorrect answer.
Use this approach when the reader’s choice is easy to name and the allowed outcomes are finite. A menu that helps customers reach the right help page may be a useful product in its own right. If most visitors already know the destination they need, a searchable help page or ordinary form may be more direct than a chat-shaped sequence. Conversation should earn the extra interaction.
2. Intent-based chatbots: varied wording, known purposes
An intent-based chatbot tries to classify a message into a purpose its system recognizes. Where is my parcel, Track my order and Has it shipped can all express an order-status intent. The response can then come from an authored answer, a structured workflow or a lookup. Recognizing natural language does not require the system to invent a new answer.
The distinction between intent and detail matters. In Book a table for four on Friday, booking is the purpose, while party size and date are values needed to carry it out. These values are often called entities, parameters or slots, depending on the platform. A classifier can identify the right purpose while extracting the wrong date, so the two results must be judged separately.
Official Amazon Lex intent documentation separates the user’s goal, required parameters, confirmation and fulfillment. That is a useful technical example of why understanding a request and completing it are distinct stages. It is not a claim that every intent-based platform uses the same controls or that a recognized intent automatically succeeds.
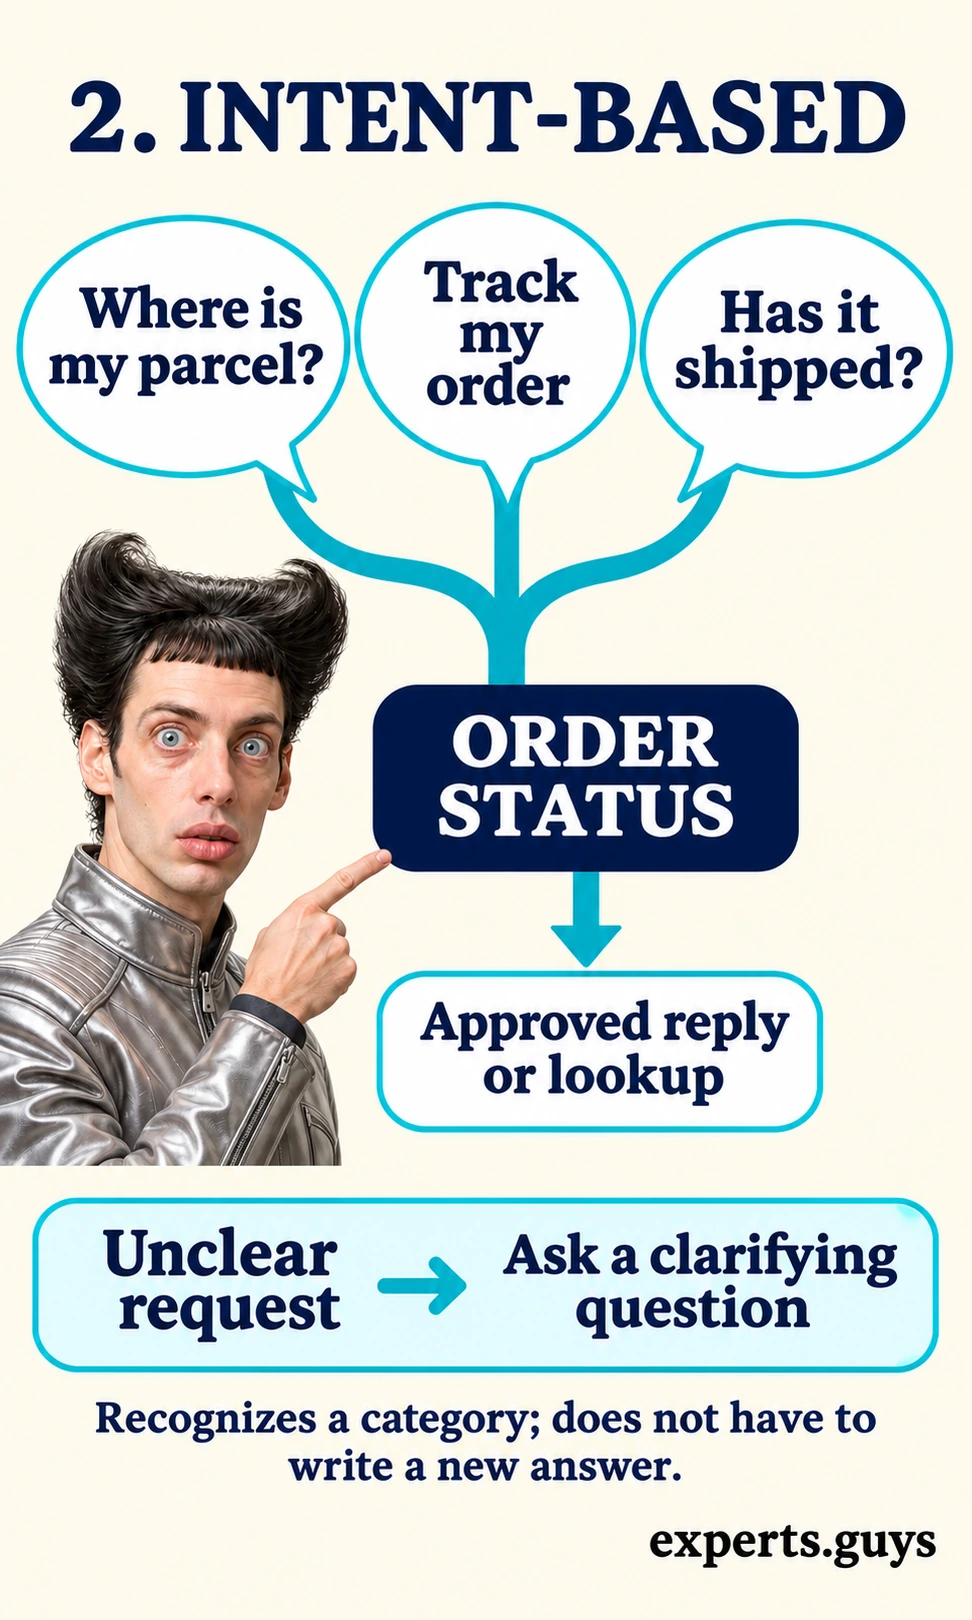
The difficult cases sit between nearby purposes. I need to send it back may mean asking about eligibility, starting a return, reporting damage or checking whether a previous return arrived. A confident category label is unhelpful if the next question assumes the wrong job. A well-designed system can ask whether the customer wants policy information or help with an existing return before collecting unrelated details.
Google’s intent-matching documentation describes matching inputs against training phrases and handling cases below a configured classification threshold. Treat the confidence output as a routing signal within that system. It is not a universal probability that the business answer will be correct, and values from different systems are not a common quality scale.
This architecture suits a recognizable set of tasks expressed in varied language. It can be a useful middle ground when a menu feels restrictive but approved wording remains desirable. Its maintenance burden includes distinguishing similar intents, improving representative examples and deciding what to do when a request is outside the supported set. Adding a category without a useful destination adds little value.
An intent catalogue should describe customer goals rather than mirror every department name. A customer may not know whether an issue belongs to logistics or account support. The routing should absorb that organizational detail. For concrete deployments, our guide to recognizing a chatbot example explains how to identify the conversational job behind a familiar interface.
3. Generative chatbots: composed responses
A generative chatbot uses a language model to compose a response from the information available to it. That may include the current request, previous messages, instructions, retrieved material and outputs from connected systems. It can explain, summarize or reformulate rather than selecting only a sentence written in advance. The freedom is useful when the reader needs an explanation adapted to a particular question.
Separate ordinary generation from retrieval-grounded generation. In the latter, the application first finds relevant material and supplies it as context for the reply. Retrieval-augmented generation, or RAG, describes this arrangement. It does not mean the model has been retrained on every document, and it does not establish that the selected passage was current or that the resulting explanation is supported.
The Dialogflow data-store documentation gives one concrete example of searching source content and forming a response from it. The important architectural distinction is retrieval followed by response production. Some knowledge systems return an approved answer unchanged; others summarize. Ask which behavior applies to the content in your proposed deployment rather than assuming that every document-based bot works alike.
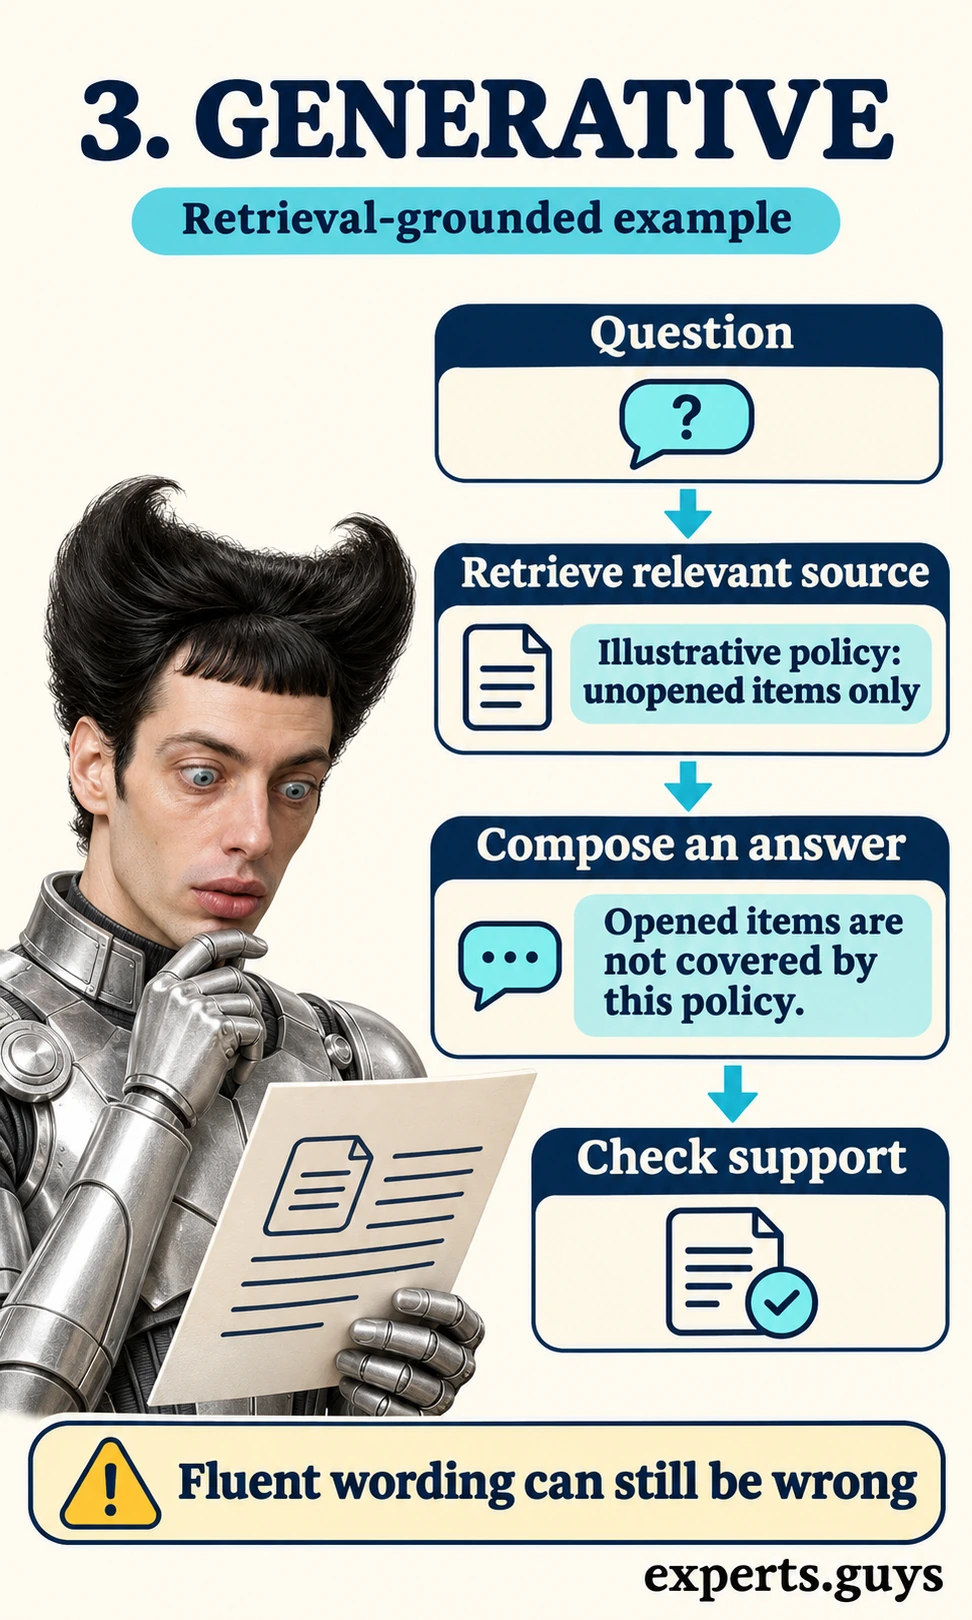
Suppose an illustrative policy states only that unopened items qualify for a particular voluntary return option. A grounded answer can explain that opened items are not covered by that policy. It should not turn the omission into a statement about every consumer right, every product category or an exception that the business has not supplied. The model’s ability to complete a sentence is broader than the evidence available for completing that claim.
Generation is particularly helpful when the source set contains explanations that readers need combined or restated. A question about two product-care instructions may call for a short comparison rather than two pasted help articles. The useful result is a supported explanation that preserves the relevant conditions. More words, a warmer tone or a confident conclusion are not independent signs that the answer is better.
The characteristic failure is unsupported composition: a plausible restriction, promise or connection that is absent from the evidence. Microsoft documents that generative answers can contain mistakes and vary between similar questions. For comparison purposes, that makes factual support and stable meaning more revealing than an expectation that every run will repeat the same sentence.
Generated wording also creates an editorial trade-off. A fixed answer can be reviewed as a complete artifact; a generated answer depends on the question and context supplied at runtime. You gain flexibility but need a way to examine representative outputs and the material behind them. This is a different maintenance task from checking whether all menu destinations still exist.
4. Hybrid chatbots: different response paths in one conversation
A hybrid chatbot combines explicit routes with language capabilities or other response mechanisms. It might explain policy using retrieved content, move an account request into a defined workflow and send an exception to a person. The label is useful only when the provider explains which approach handles each job and where the switches occur.
Hybrid does not necessarily mean a chatbot plus a live agent. Human handoff can be one part of it, but the technical combination may exist entirely within automated conversation. An intent classifier followed by a generative explanation is another combination. The boundaries between these categories are deliberately porous because real systems are built from components rather than four mutually exclusive boxes.
Google’s distinction between generative, deterministic and partly generative conversation features illustrates this separation. Input interpretation and response control can differ within one agent. That is a reason to inspect individual routes rather than treat the platform’s use of a language model as proof that every answer is freely generated.
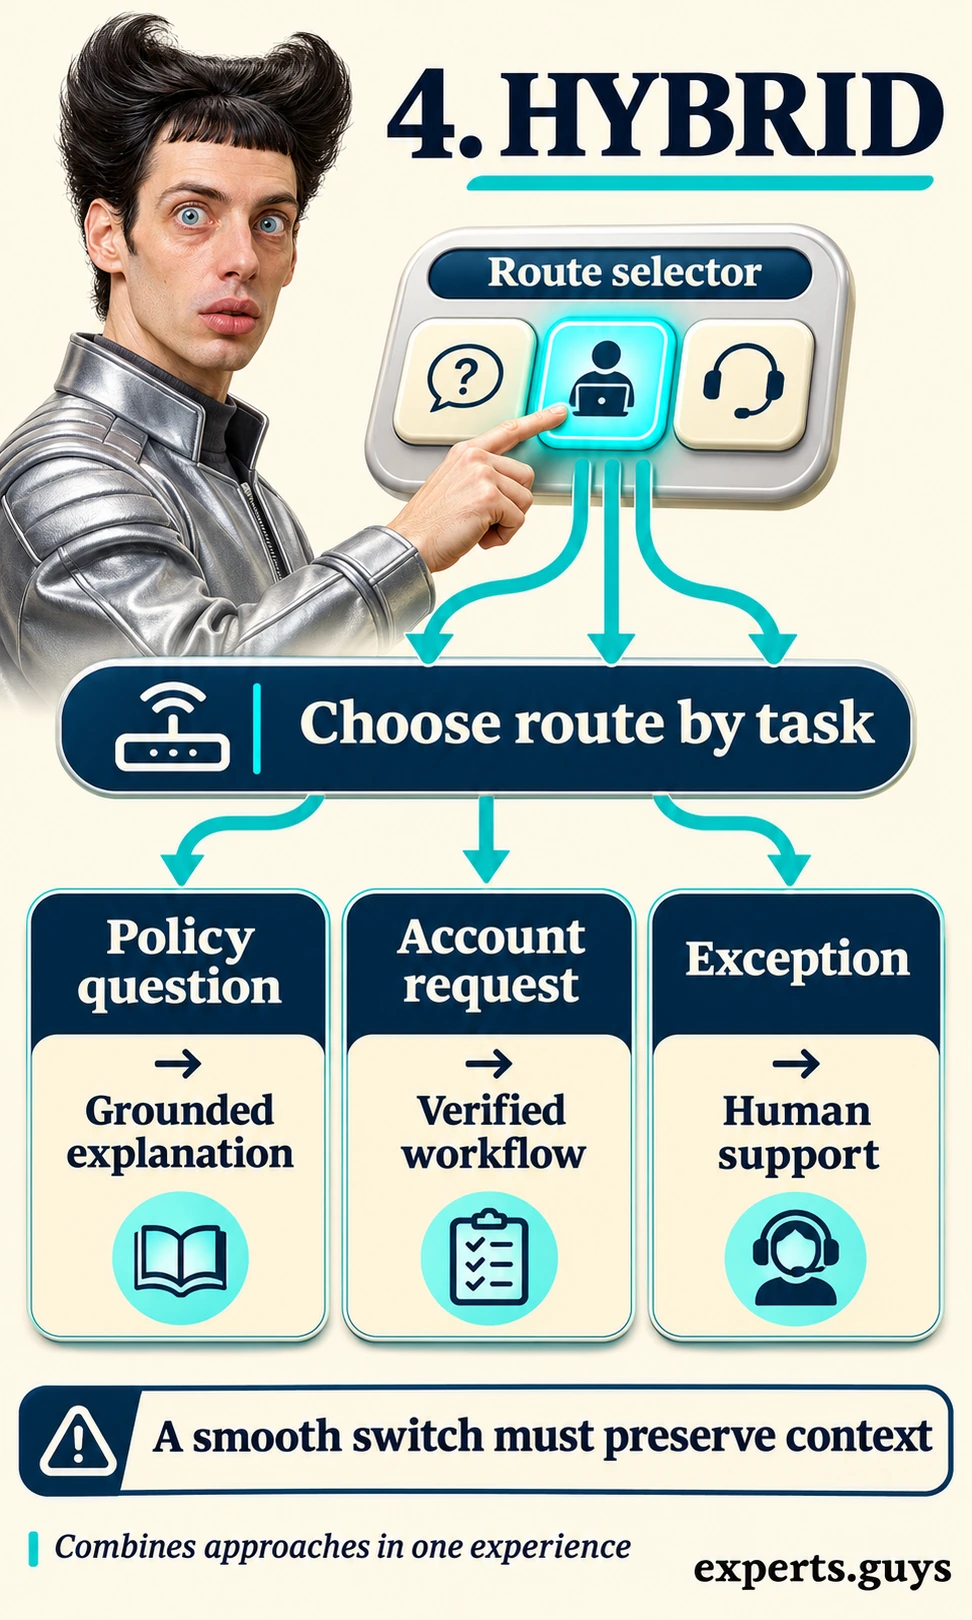
The benefit is selective flexibility. A business may welcome an adaptable explanation while wanting a precise sequence for an account change. A hybrid design can accommodate those differences. The additional cost is coordination: the application must decide when to move between routes, what information to carry forward and which response takes precedence if more than one route appears relevant.
A broken switch often feels like a memory problem. The customer explains that an item was opened, then a new route asks the same question again or assumes it was sealed. The underlying failure may be missing state transfer rather than a weak language model. Conversely, a route can retain an old detail too aggressively and apply it after the customer corrects the request. Continuity needs both preservation and revision.
For mixed tasks, a hybrid may be the most appropriate arrangement, but it is not automatically the best starting point. If one authored route fully resolves the intended conversation, extra routing layers add things to maintain. The broader operational controls belong in the customer-service implementation guide; the decision here is whether your response mechanisms need to differ at all.
Why do voice, context and memory create confusing labels?
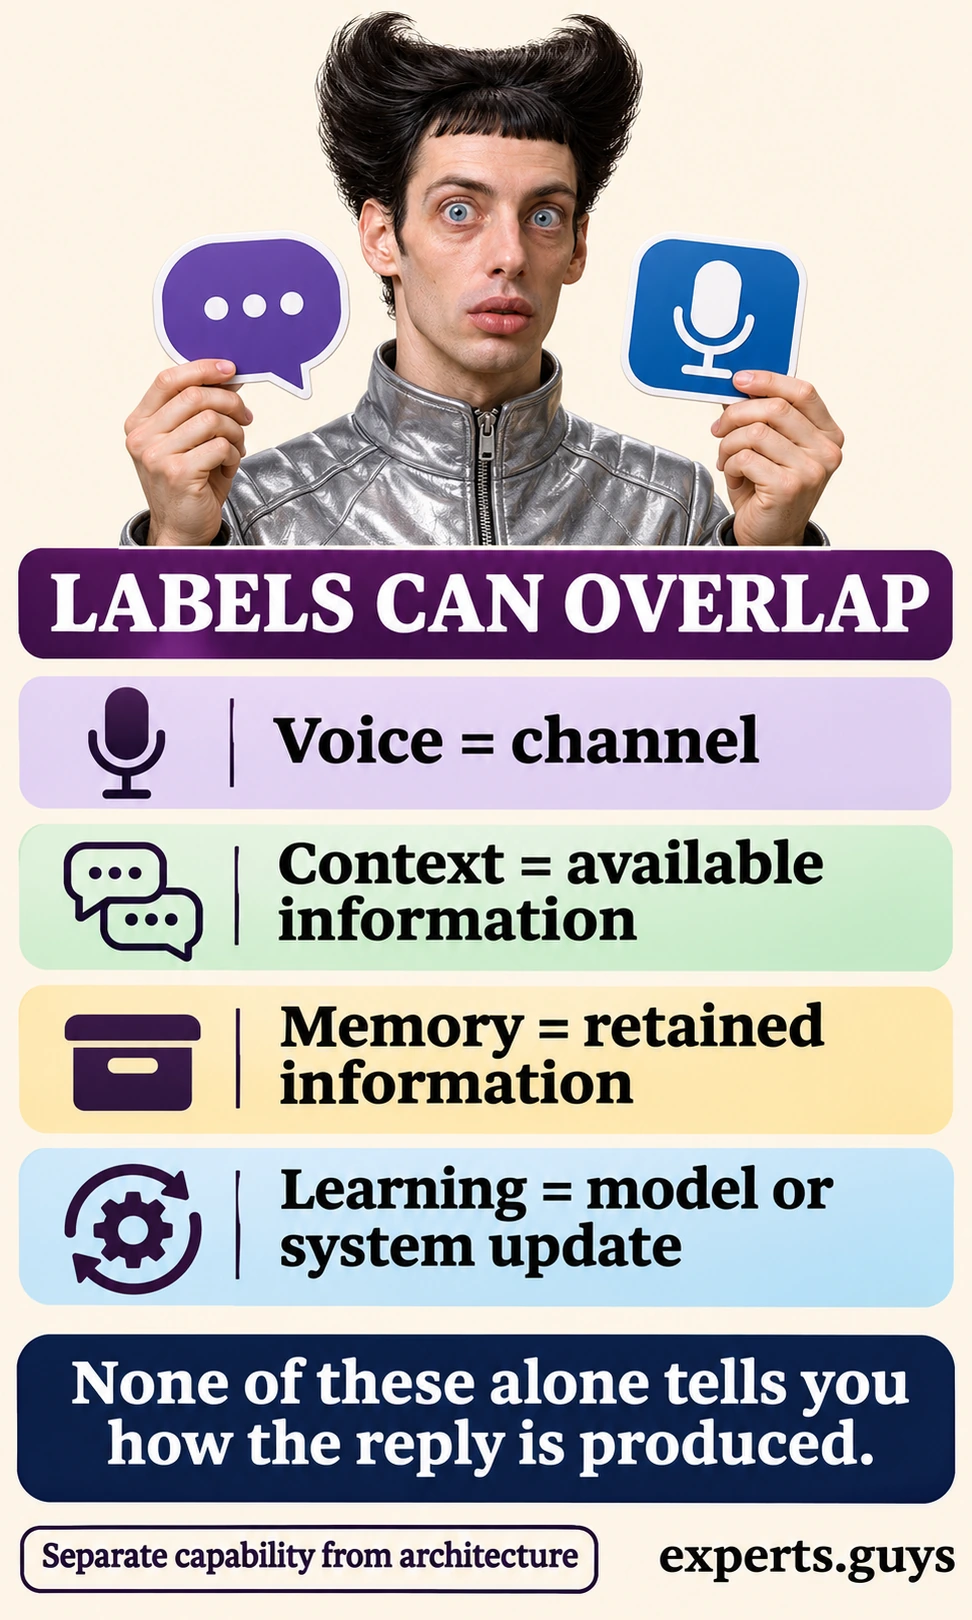
These terms answer different questions from the four-type comparison. Voice describes how the user communicates, context describes information available during the exchange, memory describes information retained for reuse, and learning describes a change to the model or surrounding system. They can overlap in one product without identifying its response architecture.
A voice interface might transcribe speech and send the resulting text into a menu-like flow, an intent matcher or a generative system. Speaking to the bot does not establish which one is running behind it. Likewise, a text interface can use sophisticated interpretation while delivering controlled responses. Channel and response mechanism should appear as separate items in a comparison.
The distinction matters when a feature is promoted as an upgrade. Adding speech can improve access for one audience while introducing recognition issues for another. It does not, by itself, make a policy explanation more accurate. Our comparison of chatbots, voice bots and virtual assistants covers the channel-level differences in more detail.
Context can be ordinary application state
Context does not have to mean a model recalling an entire personal history. A flow can store the selected product, the current question and a previously supplied date. If the user says Change it to Saturday, the application may update a date value while retaining the rest of the request. That is contextual behavior even when the eventual response is authored text.
The Amazon Lex session documentation describes conversation state, slots and switching between intents. It provides a concrete counterexample to the idea that context belongs only to free-form generative chat. The implementation still determines which information survives a switch, when a session ends and what can be restored later.
Context is also selective. A generative system has limits on what it receives for a particular response; the application may truncate, summarize or omit earlier material. A chatbot appearing to forget can reflect that information selection. A product that retains every message but fails to supply the relevant one for the current task may behave less consistently than a small flow holding a few explicit fields.
Memory is not the same as training
Remembering a preferred language on a later visit can be implemented through an account preference. Reusing a shipping detail during one session can be ordinary state. Neither behavior proves that the model’s parameters changed. Persistent memory also raises separate questions about consent, visibility, correction, deletion and who can access the stored information.
Treat claims that a bot learns from every conversation as incomplete until the provider identifies the mechanism. The claim might refer to human review of failed routes, updates to a knowledge collection, changes to prompts or later model training. Those changes have different timelines and consequences. An improvement process is not the same thing as uncontrolled real-time modification of the system after every message.
The practical consequence is that you should not enter a correction once and assume every future user will receive it. A correction might affect only the current context. If the underlying help article, authored response or structured record remains wrong, the error can return through another route. The owner must know which maintained component controls the disputed fact.
Prediction and agentic behavior are additional capabilities
A recommendation shown before a question may come from a rule, a ranking model or an account event. Its proactive timing does not define the mechanism producing the conversational explanation. Similarly, an agentic system may choose actions or use tools while presenting the result through a chatbot. The interface, autonomy and response style are related design choices with different boundaries.
Do not infer awareness, emotional understanding or independent authority from a convincing response. A bot can produce sympathetic wording without establishing what a person feels, and a fluent request for an account action is still a request. For this taxonomy, keep those claims outside the comparison unless they are translated into observable, limited capabilities that a provider can demonstrate.
How would the four types handle the same question?
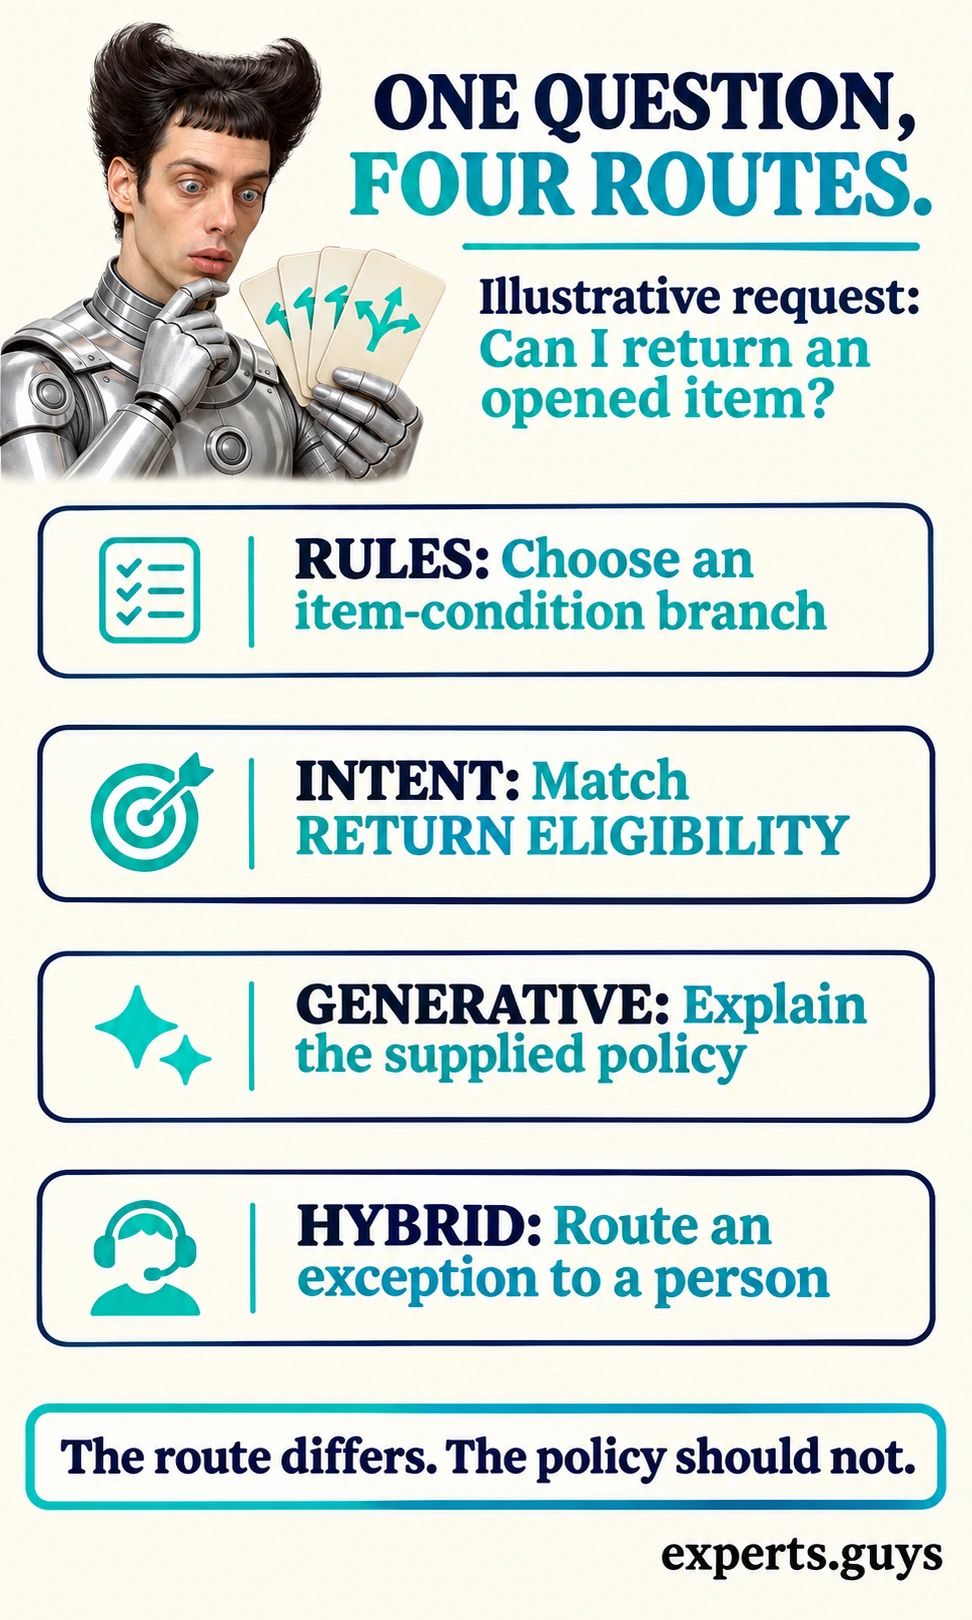
Use one scenario to separate route differences from answer quality. Imagine a fictional retailer whose supplied voluntary policy covers unopened items, with opened-item exceptions sent to staff for consideration. A customer asks, Can I return an opened item? This is an architectural illustration, not a statement about a real retailer, legal entitlement or measured product performance.
Hold the policy and customer question constant. The comparison is then about how the system reaches a response and handles the exception. If one demonstration quietly adds a more generous policy, extra customer information or an integrated service desk, the result is no longer evidence that its chatbot type alone is better. Different inputs can produce a different experience without a better response mechanism.
The rule-based route makes the missing choice visible
The menu asks the customer to select Returns and then item condition. Choosing Opened reaches an authored response explaining that the standard option does not apply and showing the available staff route. A useful version makes that route reachable without forcing the customer to pretend the item is unopened. A poor version ends the conversation because its designer omitted that branch.
The revealing distinction is coverage. If the opened-item branch is missing, making the bot more conversational will not create a valid business decision. The appropriate correction may be an explicit exception destination. For a compact catalogue of outcomes, that can be a smaller and more transparent change than replacing the whole conversation with a language model.
The intent-based route must identify the right purpose
The system maps the wording to return eligibility and extracts opened as a condition. If it instead selects return tracking, it may ask for a return reference before answering the policy question. The wording can sound polished while the route is wrong. Intent and detail must both remain aligned with the actual question.
When the customer says I need help sending it back, a clarification may be the appropriate result because the purpose is less specific. That extra question is not necessarily a failure. It can distinguish policy explanation from starting an existing process. What matters is whether the clarification removes uncertainty rather than demanding information the user already supplied.
The generative route must stay within the supplied policy
The bot can explain that the ordinary voluntary policy covers unopened items and that staff consider the stated exceptions. It may tailor the explanation to the opened condition without requiring a menu selection. That flexibility becomes a problem if the bot invents a special deadline, promises an exception or treats the policy as a complete statement of legal rights.
The check is whether each consequential part of the answer has support. A correct first sentence does not excuse an invented second sentence. Nor does a link to the policy establish that every claim in the generated reply follows from it. Inspect the relationship between source and statement, especially the condition that changes the customer’s next action.
The hybrid route must preserve the reason for switching
The conversation can explain the policy first, then move the exception request to a defined staff route. The transition should preserve that the item is opened and that the user is asking for an exception. It should not silently convert a policy explanation into an approved return or announce a successful transfer when only a routing request has been issued.
This scenario supports a bounded editorial recommendation: favor explicit control for a small, stable set of outcomes; add language flexibility when interpreting or explaining varied requests is a real obstacle; combine routes when the tasks demand different treatment. The recommendation changes when the source material, audience, channel or required actions change. No architecture overrides the business policy it is supposed to explain.
How can you compare a chatbot without trusting its label?
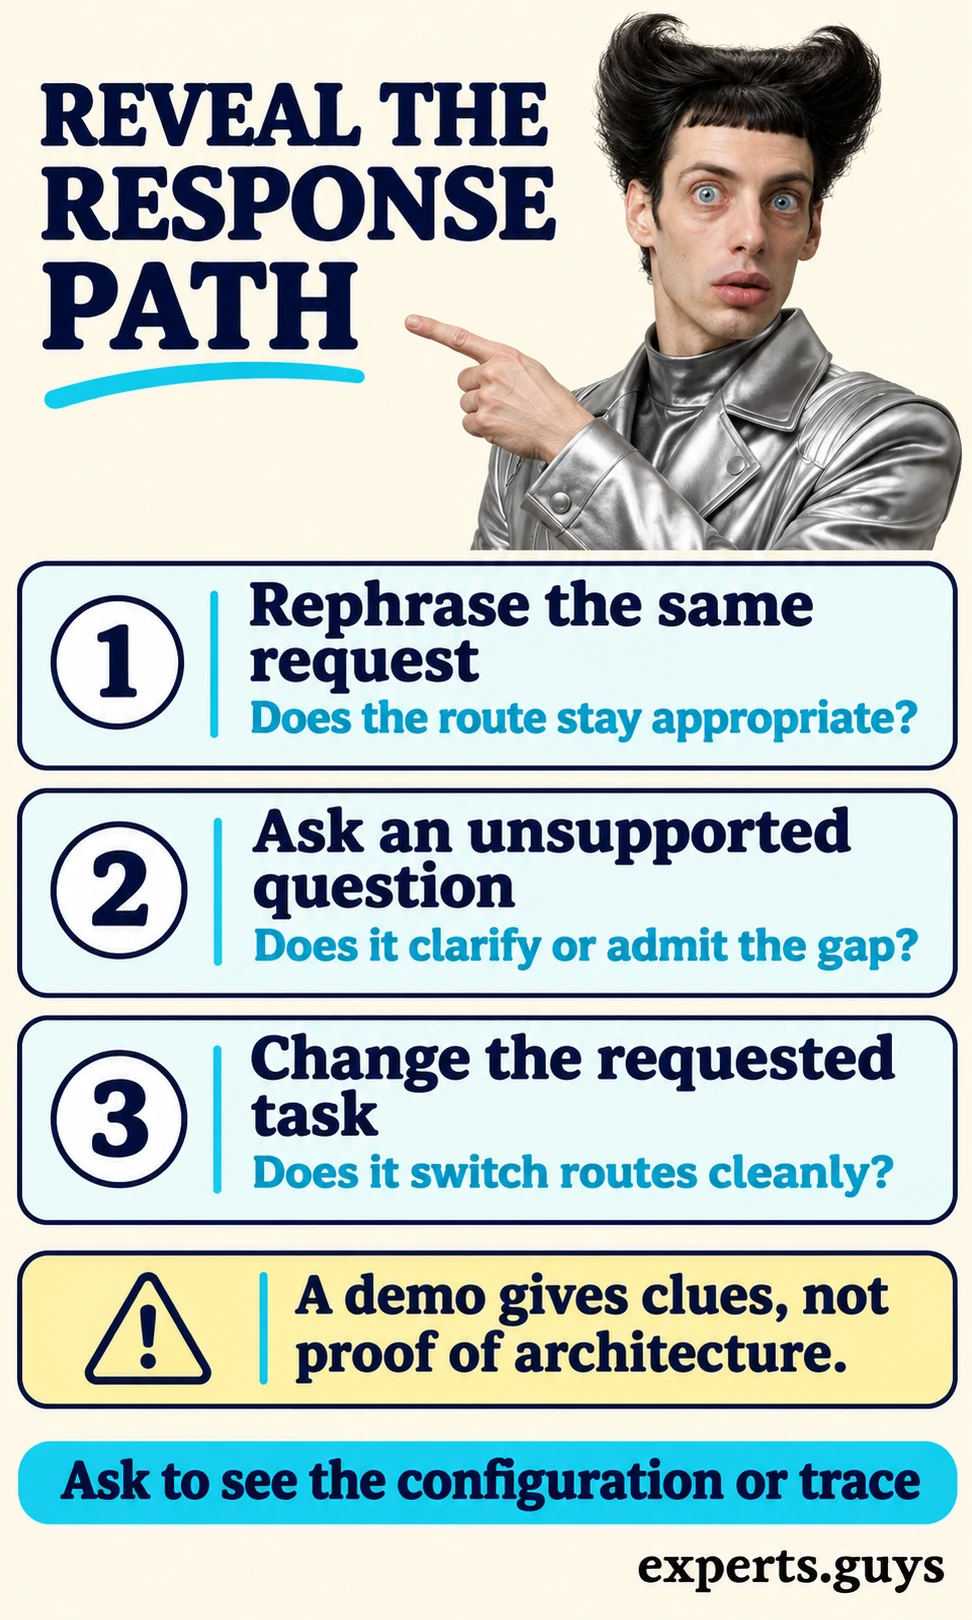
Ask to see the response path for a representative conversation, then use a small set of deliberate variations. The aim is to understand what the configured system does, not reverse-engineer a hidden model from its writing style. A demonstration can reveal useful clues, but similar visible behavior can come from different implementations.
Before the comparison, use a public or synthetic request and agree on the relevant source material. Avoid real customer details and do not request an actual purchase, refund or account change. You only need enough context to see the routing decision. If a provider cannot expose a trace, a configuration walkthrough is a useful lower-effort alternative, with the limitation kept explicit.
- Rephrase the same request. Keep the facts fixed and observe whether the selected purpose remains appropriate.
- Ask an unsupported question. Look for a clarification or an admitted gap, and ask what source supported any definite answer.
- Change the requested task. Move from policy explanation to an exception request and observe the route switch and retained condition.
For the first variation, rephrase the same purpose without changing its facts. Compare Can I return an opened item with Is an unsealed item eligible? The desired outcome is appropriate handling of the same condition, not necessarily identical wording. An irrelevant route exposes an interpretation gap; different but supported explanations may be acceptable.
For the second variation, ask about a condition deliberately absent from the supplied source. The useful behavior is a clarification or a stated limit rather than a fabricated answer. A system that confidently replies may be using another approved source, so ask to see it before deciding that the answer is invented. The evidence is the actual response path and support, not your expectation about which mechanism it used.
For the third variation, change the job: after asking about eligibility, ask for an exception. Observe whether the system keeps explaining the rule, enters another route or offers staff help. Check whether it carries the relevant condition into that route. In this comparison exercise, stop before any consequential action; a simulated transition is sufficient to expose the design.
Completion means you can describe the selected route, the information used and the boundary of what it establishes. If the result remains unclear, ask for the configuration or trace rather than collecting more polished answers. This three-part demonstration is an editorial inspection method, not a validated benchmark, a security assessment or proof of production reliability.
| Observation | Useful interpretation | What remains unproven |
|---|---|---|
| A rephrased request reaches the right destination. | The demonstrated wording is handled appropriately. | Coverage of other languages, phrasing and edge cases. |
| The bot asks for clarification. | It exposes a gap instead of silently selecting a route. | Whether it clarifies at the right time across the full case mix. |
| A reply shows a supporting source. | There is a candidate basis for checking the claim. | Whether every statement follows from that source. |
| The task switches without losing the condition. | State transfer works for this demonstrated transition. | Other transitions, session expiry and production behavior. |
| A configuration or trace identifies the response component. | There is inspectable implementation evidence. | Whole-system security, reliability or business value. |
Swipe horizontally to compare on narrow screens.
What does the type imply about maintenance and cost?
It indicates where work may accumulate, not a fixed price or guaranteed saving. Rule-based systems require branch and content upkeep; intent-based systems add category and language-example work; generative systems add source and output assessment; hybrids add the coordination between paths. A provider can package those jobs in different commercial models, so architecture labels do not establish the total operating cost.
Compare like-for-like scope. A simple public-information menu and an integrated account assistant have different obligations even if both are sold as chatbots. Ask what the quote includes for maintaining responses, changing source material and explaining failures. A lower software fee can coexist with substantial internal editing work, while a higher fee may include services that another proposal leaves to your team.
The same discipline applies to speed. A short authored reply may return quickly, while a generated response that retrieves documents or calls services can involve more work. Actual latency depends on the configured path, infrastructure and load. Without a comparable measurement, avoid turning that architectural observation into a claim that one type is always faster or cheaper.
When should you choose a simpler interface?
If the user only needs one known value or one direct action, a visible page, search box or ordinary form may resolve the job with fewer turns. A chatbot becomes useful when the exchange helps interpret the need, explain a condition or move between related tasks. The number of messages is a means of completing that job, not a benefit to maximize.
Keep that comparison available when reviewing impressive demonstrations. An elaborate conversation can conceal that the customer wanted a direct link. Equally, an ordinary help page may leave a reader struggling to combine several conditions. Choose the interface that reduces the actual uncertainty, then select the response mechanism that supports it.
Frequently asked questions
Is keyword matching the same as intent recognition?
Not necessarily. A keyword rule reacts to a specified word or pattern, while intent recognition tries to map a message to a purpose. A product can combine both. Negation and nearby purposes are useful examples to inspect because the same word can appear in requests that need different handling.
Can a chatbot have buttons and still be generative?
Yes. Buttons may start a topic, supply a condition or offer a next action while another part of the conversation composes responses. Inspect what the button triggers and what produces the following answer. The visible control does not identify the whole response architecture.
Does an API connection make a chatbot an AI agent?
A connection alone does not establish agentic behavior. A fixed workflow can call an API at a predefined step. The separate question is how much discretion the system has to choose and sequence actions. Regardless of that discretion, access rights and action results need controls outside the wording of the conversation.
Is a knowledge-base chatbot always generative?
No. It may select an existing answer or retrieve a document without rewriting it. Another configuration may retrieve material and compose an explanation. Ask whether the response is copied, assembled from a template or newly composed, and which source version supplies its facts.
Can you identify the chatbot model from its replies?
You generally cannot establish the exact model or architecture from a few replies. Instructions, templates, retrieval and post-processing can make different systems sound similar. Provider documentation, the configured route and an appropriate trace are stronger evidence than guesses based on tone or formatting.
Are four chatbot types enough for every comparison?
No single list captures every dimension. This framework separates common response mechanisms; a detailed procurement review may also need language support, accessibility, deployment, data handling, integrations and operating requirements. Add those as separate criteria rather than treating a longer type list as a more precise ranking.
Choose the response path before the product label
For your next comparison, ask the provider to finish one sentence: This request is interpreted by this component, answered from this information, and passed to this route when it exceeds scope. If the explanation is clear, you have something concrete to inspect. If it remains a list of capabilities, return to the conversation example before choosing the architecture.