AI in customer service uses software to interpret requests, retrieve information and help people reach a useful answer. It can improve customer satisfaction by reducing waiting, repeated explanations and uncertainty, but only when the customer gets an accurate outcome and retains a clear route to human help.
The strongest improvement is often less work for the customer: fewer unnecessary steps, a clearer status and an answer that matches what the business can actually do. A quick greeting followed by a dead end delivers very little of that value.
For a service manager, the useful question is not simply whether the chatbot answered more messages. It is whether comparable customers finished their tasks with less effort, fewer broken promises and fewer reasons to return about the same problem.
Where does AI reduce customer effort?
AI can help at several different moments. It can interpret a loosely worded request, surface the relevant policy for an agent, summarize established context or identify repeated complaints that deserve a product fix. These are mechanisms, not guaranteed results; poor source information or a confusing interface can cancel out the benefit.
Around-the-clock availability is valuable for tasks the system can genuinely complete outside staffed hours. If a warehouse decision or human exception is still required, the benefit is an accurate status and a clear next route, not an invented promise of immediate completion. Multilingual replies can also reduce effort, provided their meaning and task completion are checked in the languages being served.
Start with the friction the customer experiences rather than a list of AI features. One request can contain several kinds of friction, but choosing a single recurring obstacle makes the first improvement easier to judge.
- Waiting: the customer cannot obtain a supported answer when needed.
- Repeating: the customer provides information the service already holds and is permitted to reuse.
- Searching: the reply sends the customer through unnecessary menus or documents.
- Uncertainty: the customer cannot tell whether an action happened or what remains pending.
- Loss of control: the customer cannot change direction or reach appropriate human help.
Replay one request from the customer’s side
Use an approved test account or an appropriately redacted case to replay the actual journey, starting with the original customer goal. Open each route the reply asks the customer to use, check whether information must be entered again and follow the journey through to its real completion state. For a replacement request, opening a chat and receiving an approval message does not establish that a parcel has left the warehouse.
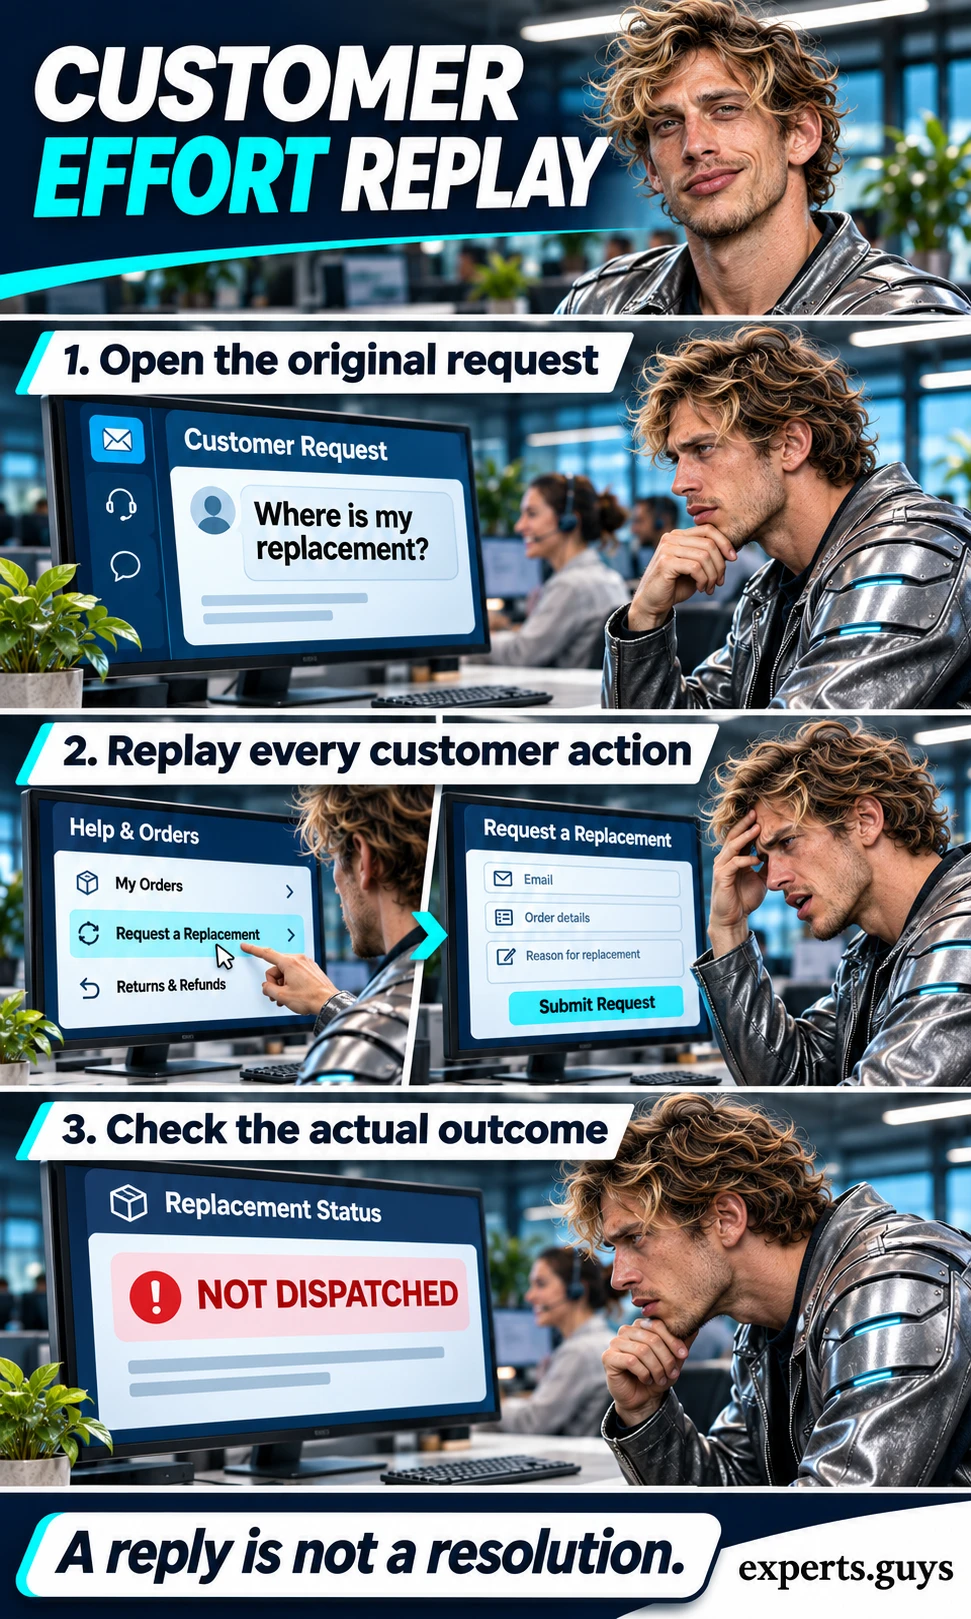
The checkpoint is an observable result: the customer can see the correct dispatch state, complete the permitted action or reach the person who can decide the exception. Do not count typing fewer words as a success if the customer has to switch channels and start again. If you cannot access a safe test environment, replay the approved transcript against its existing case history rather than performing live account changes.
Replace a broad menu with one relevant next action
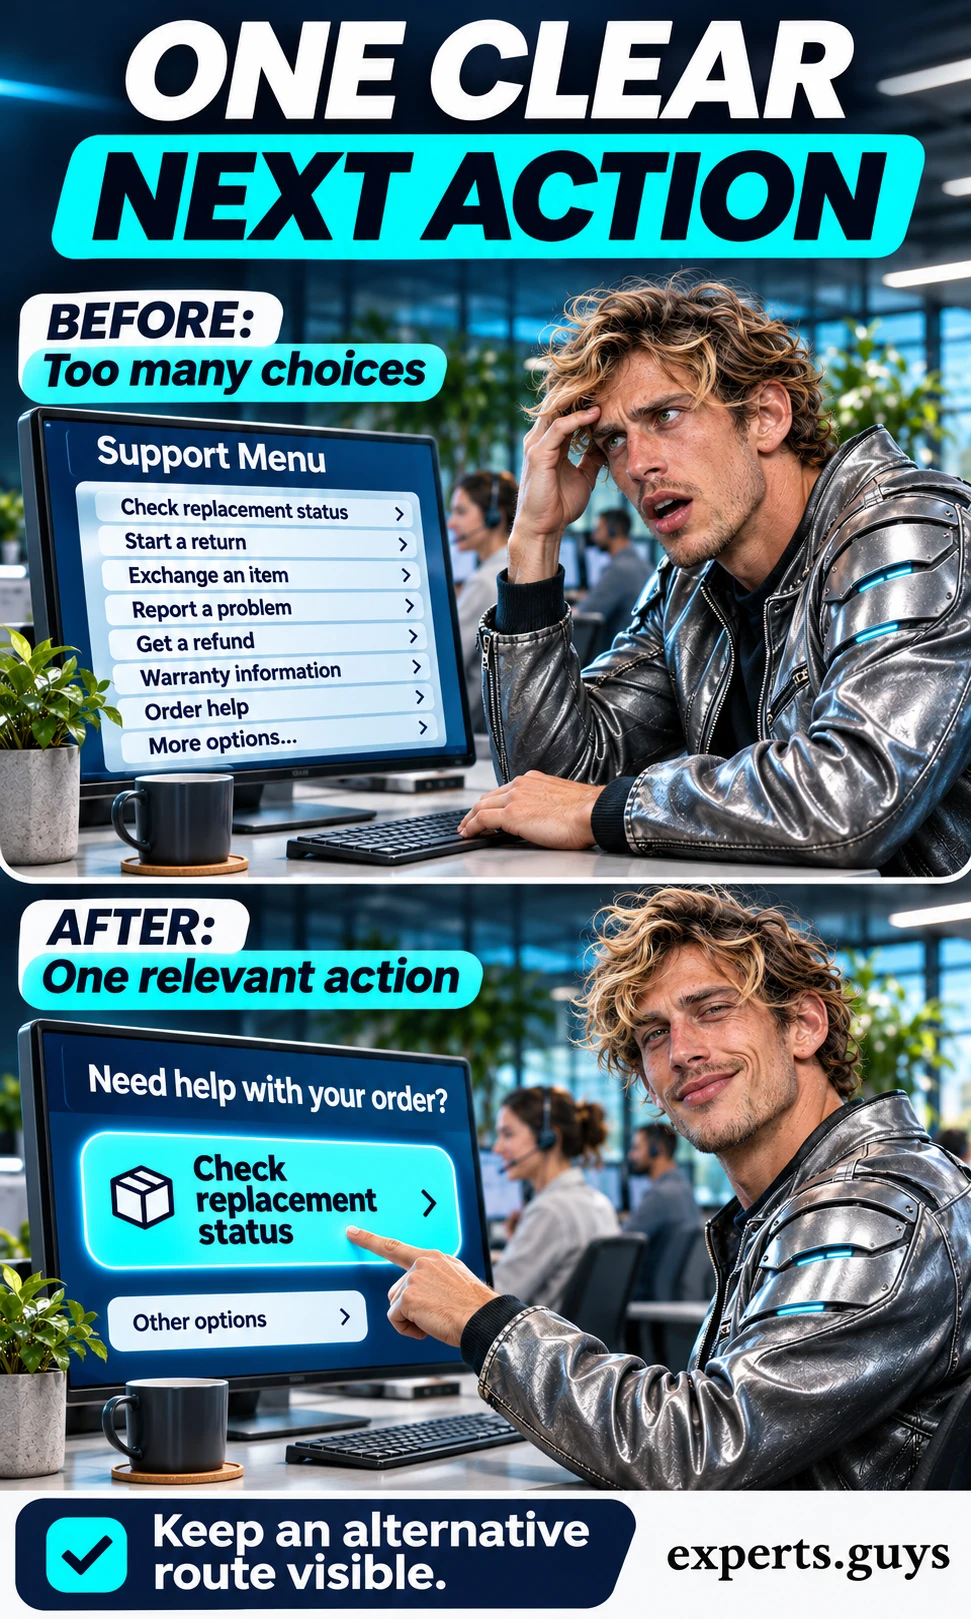
After the request is understood, lead with the action that advances that request. In the replacement example, “Check replacement status” is more useful than a long list of delivery, billing and returns topics. Show the other routes as alternatives so a mistaken interpretation does not trap the customer.
Try the revised path using the same request and a plausible ambiguous version of it. A useful change removes unnecessary choice without suppressing information the customer needs. If the request remains ambiguous, ask one discriminating question, such as whether the customer wants the original order or the replacement, instead of guessing and hiding the alternatives.
Agent assistance can improve the conversation without becoming the customer’s front door. In the published Generative AI at Work research, assistance for customer-support staff improved measured productivity and some customer-interaction outcomes, with effects varying by worker experience. That evidence concerns a particular agent-assistance setting; it does not establish a universal CSAT gain or the same effect for an autonomous chatbot.
Keep the customer-outcome question separate from the deployment question. The AI customer-service implementation guide covers sources, permissions and rollout boundaries. Here, the job is to identify which part of the experience actually became easier after those controls were put in place.
Why can a faster answer still disappoint customers?
Speed improves an experience only when the answer helps the customer make progress. A fluent but inaccurate message can create a second failure: the original problem remains, and the customer now expects something the business has not done. The following distinctions prevent a dashboard from giving credit to the wrong outcome.
| Signal | What it tells you | What still needs checking |
|---|---|---|
| Fast first reply | The customer received a response quickly. | Was it useful and correct? |
| Conversation ended | The interaction stopped. | Was the issue solved, abandoned or moved elsewhere? |
| Positive language | The wording sounds favorable. | Did the customer give a rating, and did the outcome hold? |
| Fewer human transfers | Fewer cases reached agents. | Could customers still obtain human help when needed? |
| Higher CSAT | More respondents selected satisfied ratings. | Who was invited, who answered and who returned? |
Check the promise against the source record
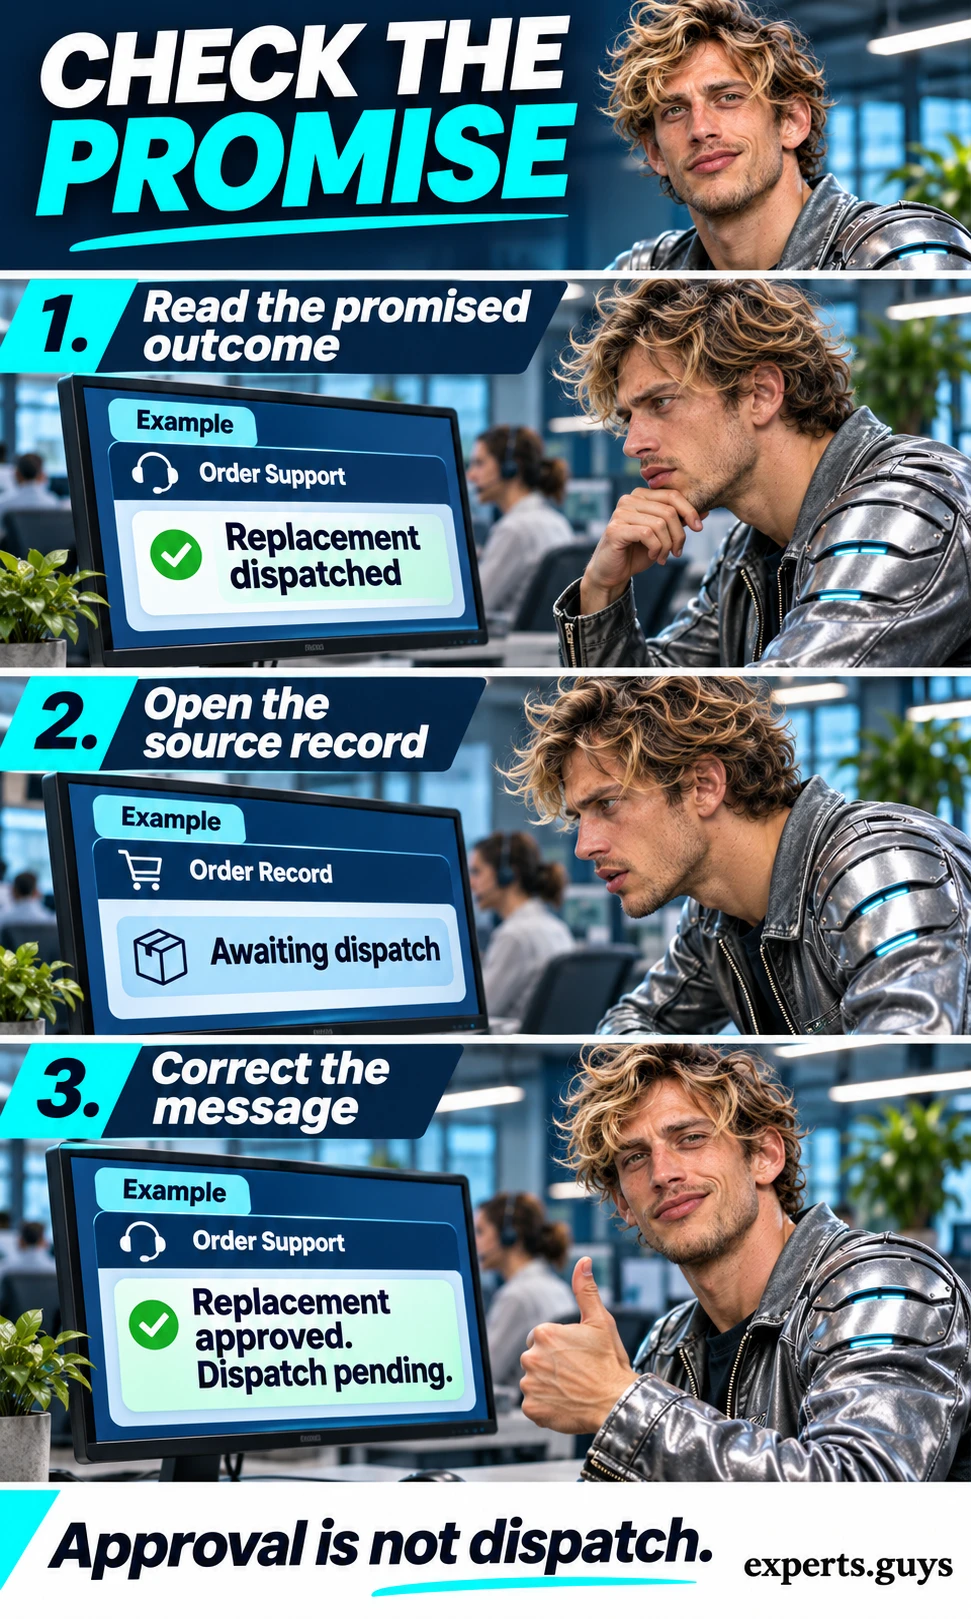
Review a customer-facing statement that claims an action or outcome, then open the authorized record that can verify it. Compare the exact state, including the distinction between requested, approved, processing and completed. This catches promises that sound helpful but merely move uncertainty into the customer’s next interaction.
For example, a reply saying “Your replacement has dispatched” is wrong when the order record says “Awaiting dispatch.” Correct the message to “Your replacement is approved; dispatch is pending” and provide the supported status route. If the record is unavailable, say what cannot yet be confirmed instead of replacing missing evidence with a reassuring sentence.
Make the same check when a reply gives a deadline, a fee waiver or an exception. A sample of ordinary status messages is a manageable starting point for a small team. When a mismatch repeats, fix the source mapping or response rule that causes it and replay the affected cases; coaching the wording alone will not repair a wrong underlying status.
Test whether customers can leave the automated route
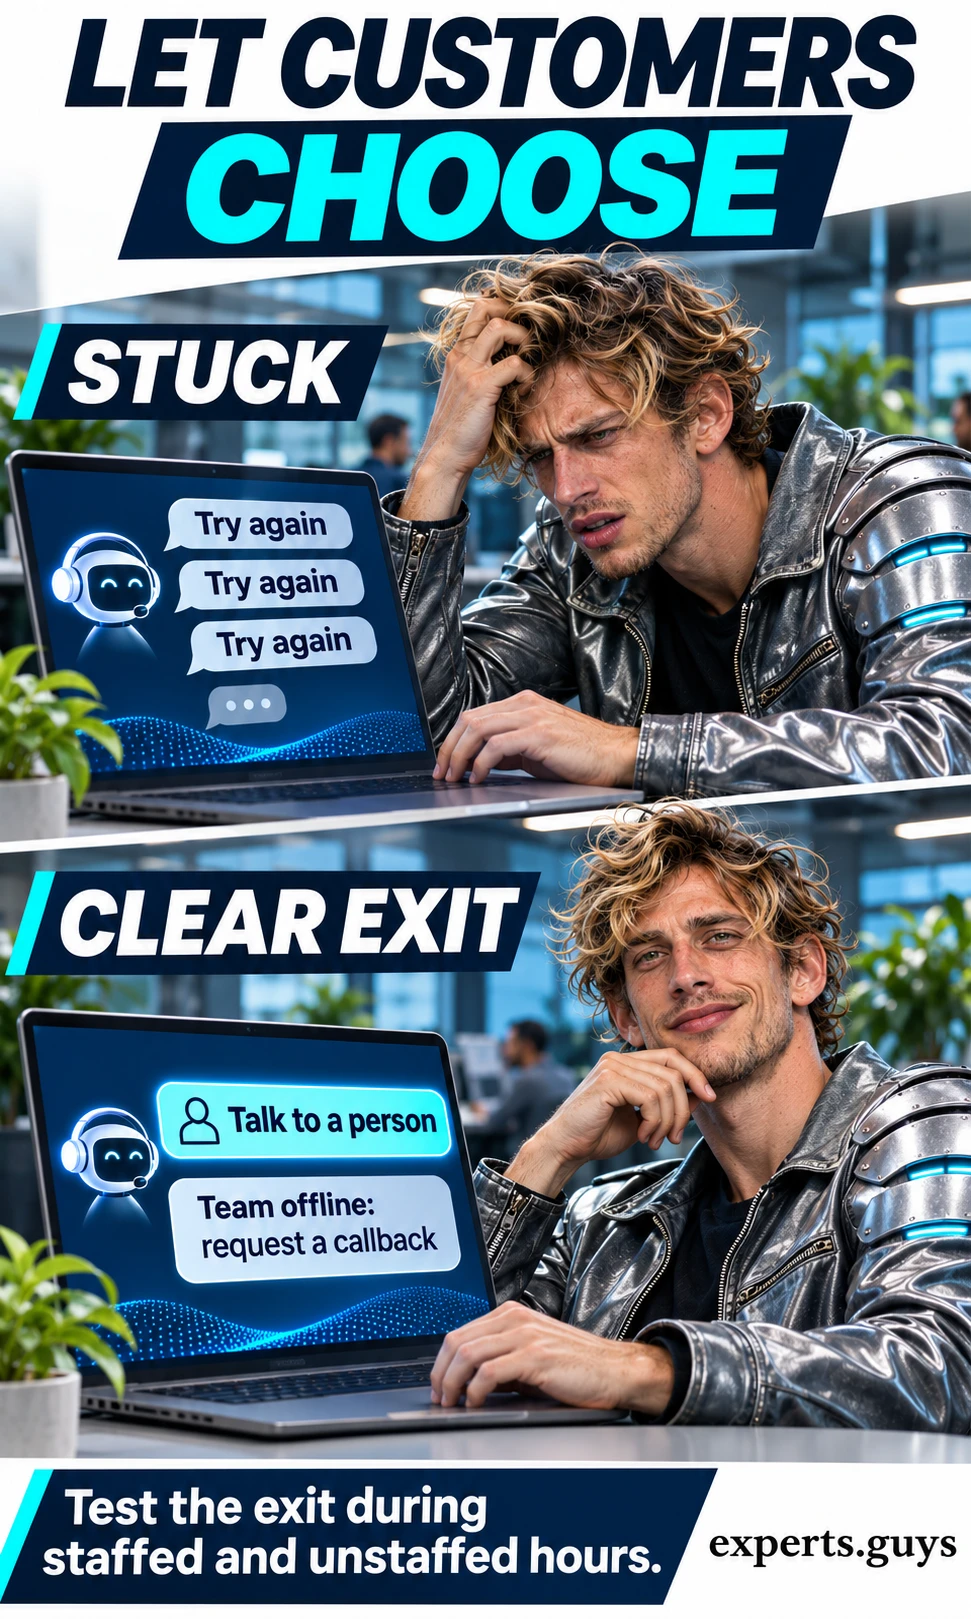
Enter the experience through the route a customer actually sees and ask for human help. Check that the option is visible, understandable and usable, then repeat the check outside staffed hours. The customer should see the real available alternative, such as an existing callback request route, rather than a transfer message that leads to an unattended queue.
Also try a simple misunderstanding: ask about a replacement when the system thinks the request concerns a return. The customer should be able to correct that interpretation without restarting every step. A one-click exit is not a universal requirement, but repeatedly asking the same question after a clear request for help is a recognizable control failure.
Keep this test focused on the customer’s ability to choose. Detailed integration and queue design belong in the implementation guide; the acceptance check here is whether the customer reaches an honest, usable next step. If the system cannot provide that path, narrow what it offers until the gap is repaired.
Personalization has the same boundary. Remembering an authorized order context can remove repetition; guessing someone’s mood, needs or willingness to accept an offer may create new friction. Use the information needed for the current request and let the customer correct the interpretation. An inferred sentiment label should never replace the customer’s explicit request or rating.
How do you know satisfaction genuinely improved?
Use reported satisfaction alongside the population behind it and the outcome after the conversation. Customer satisfaction score, or CSAT, summarizes feedback from respondents. It does not automatically represent everyone who received service, and it cannot by itself tell you whether AI caused a change.
Audit the denominators before comparing scores
For a five-point survey, define satisfied as ratings of 4 or 5 and keep that rule unchanged across groups. The standard percentage CSAT calculation is satisfied responses divided by valid responses, multiplied by 100. Export aggregate counts from the existing service or survey system: eligible cases, invitations, valid responses and satisfied responses. Count each case under one documented rule so duplicate messages do not become extra customers.
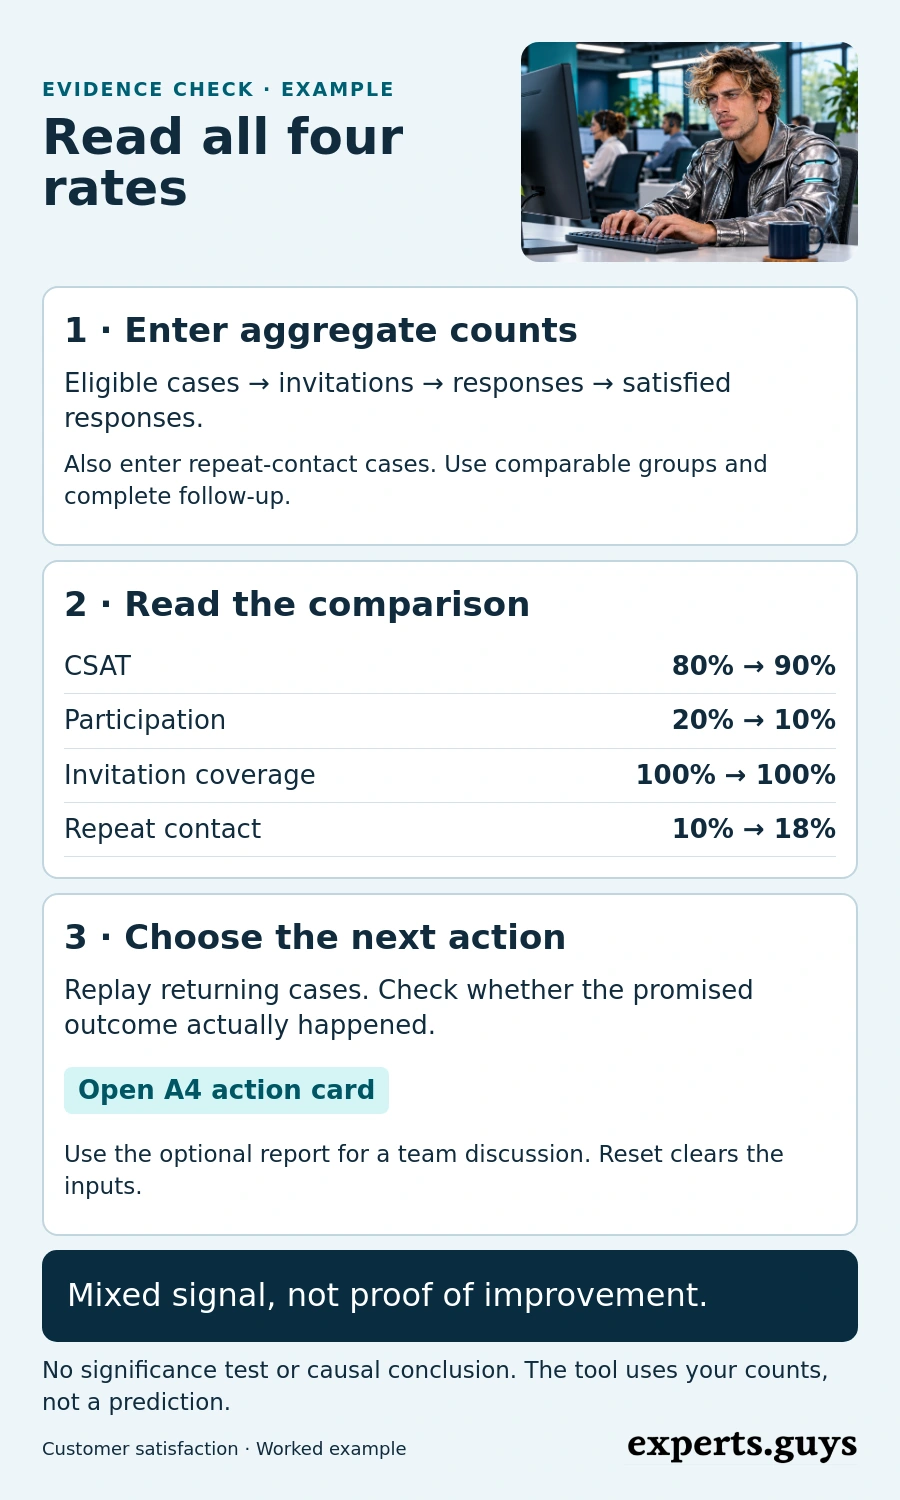
Consider an illustrative baseline with 1,000 eligible cases, 1,000 invitations, 200 responses and 160 satisfied responses. Its CSAT is 80%, while survey participation is 20%. A comparison group with 1,000 invitations, 100 responses and 90 satisfied responses has 90% CSAT and 10% participation. The CSAT difference is 10 percentage points, but you have feedback from a smaller share of the invited group.
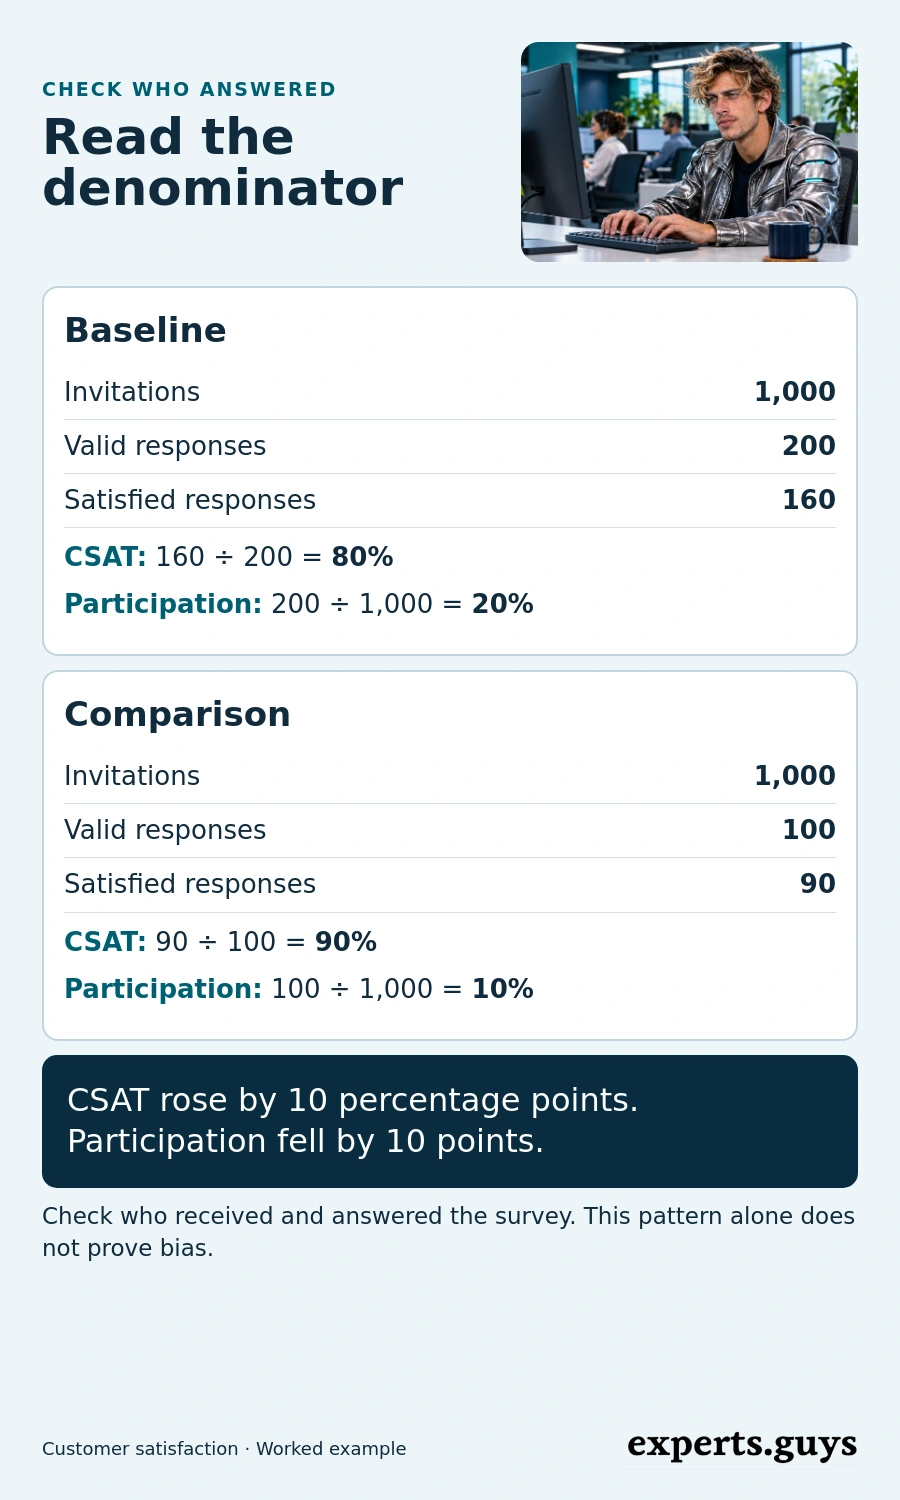
That pattern is a reason to investigate, not proof that the improvement is false. Nonrespondents might have different experiences, or they might not. Survey-method guidance on nonresponse explains why a response rate alone cannot establish whether nonresponse bias exists. Check which case types were invited and whether invitation timing changed before interpreting the increase.
Invitation coverage is a separate check: invitations divided by eligible cases. If only completed chatbot sessions receive a survey, abandoned or transferred cases may be absent before participation is even calculated. Keep the feedback opportunity consistent across the comparison, including relevant unsuccessful outcomes, while respecting the organization’s contact and data-use rules. If your system cannot identify invitations reliably, label participation as unavailable rather than dividing by a convenient substitute.
Compare similar cases over the same follow-up window
First group cases by the factors that change difficulty: issue type, channel, language and any relevant customer or product context. Compare the same group before and after the change, or use a suitable contemporaneous comparison. Do not compare automated delivery-status queries with human-handled billing disputes and call the resulting gap an AI effect.
Then define repeat contact at the case level: an eligible customer issue that returns through a trackable channel within a stated observation window. Choose the window to fit the task and apply it to both groups; a replacement that takes time to ship needs enough follow-up to reveal the relevant problem. Avoid comparing a fully observed baseline with fresh cases whose follow-up is still incomplete.
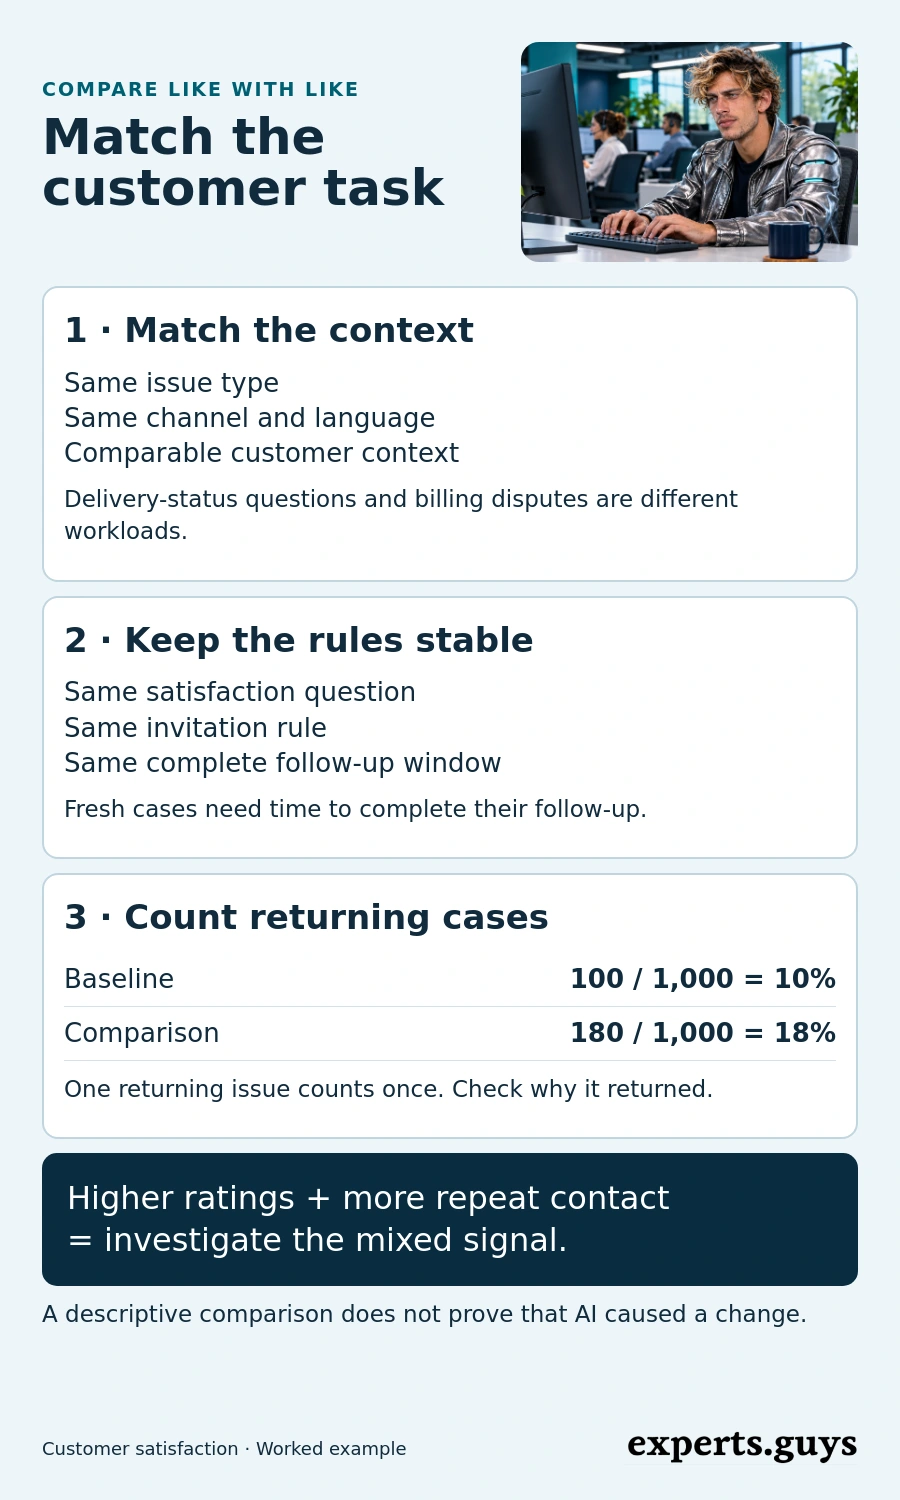
Suppose the two illustrative groups each contain 1,000 eligible cases. If 100 baseline cases and 180 comparison cases return about the same issue, repeat-contact rates are 10% and 18%. Combined with the CSAT example, the signals disagree: ratings are higher among respondents, but returning cases are more frequent. Investigate the returning cases before presenting the score change as a broad service improvement.
Repeat contact is not automatically a failure; a legitimate new detail may require another interaction. Check the reason for returning, deduplicate linked contacts and state any cross-channel gaps. Likewise, a customer-effort question can add useful feedback, but keep its wording and scale stable. Sentiment analysis of a message, a satisfaction rating and a completed outcome measure different things and should retain separate labels.
A simple before-and-after comparison remains vulnerable to staffing changes, seasonality and a different mix of requests. A randomized or otherwise carefully designed evaluation can make attribution stronger, but it needs suitable analysis and enough observations for the question being tested. Small samples are useful for finding specific failures; they are weak grounds for claiming a stable percentage improvement.
What should you improve first?
Choose a recurring friction with a visible customer consequence and a change your team can actually test. Avoid launching several changes at once and then attributing every movement in the score to AI. The practical goal is to make one customer task easier while keeping correctness and control intact.
Repair one repeated-effort hotspot
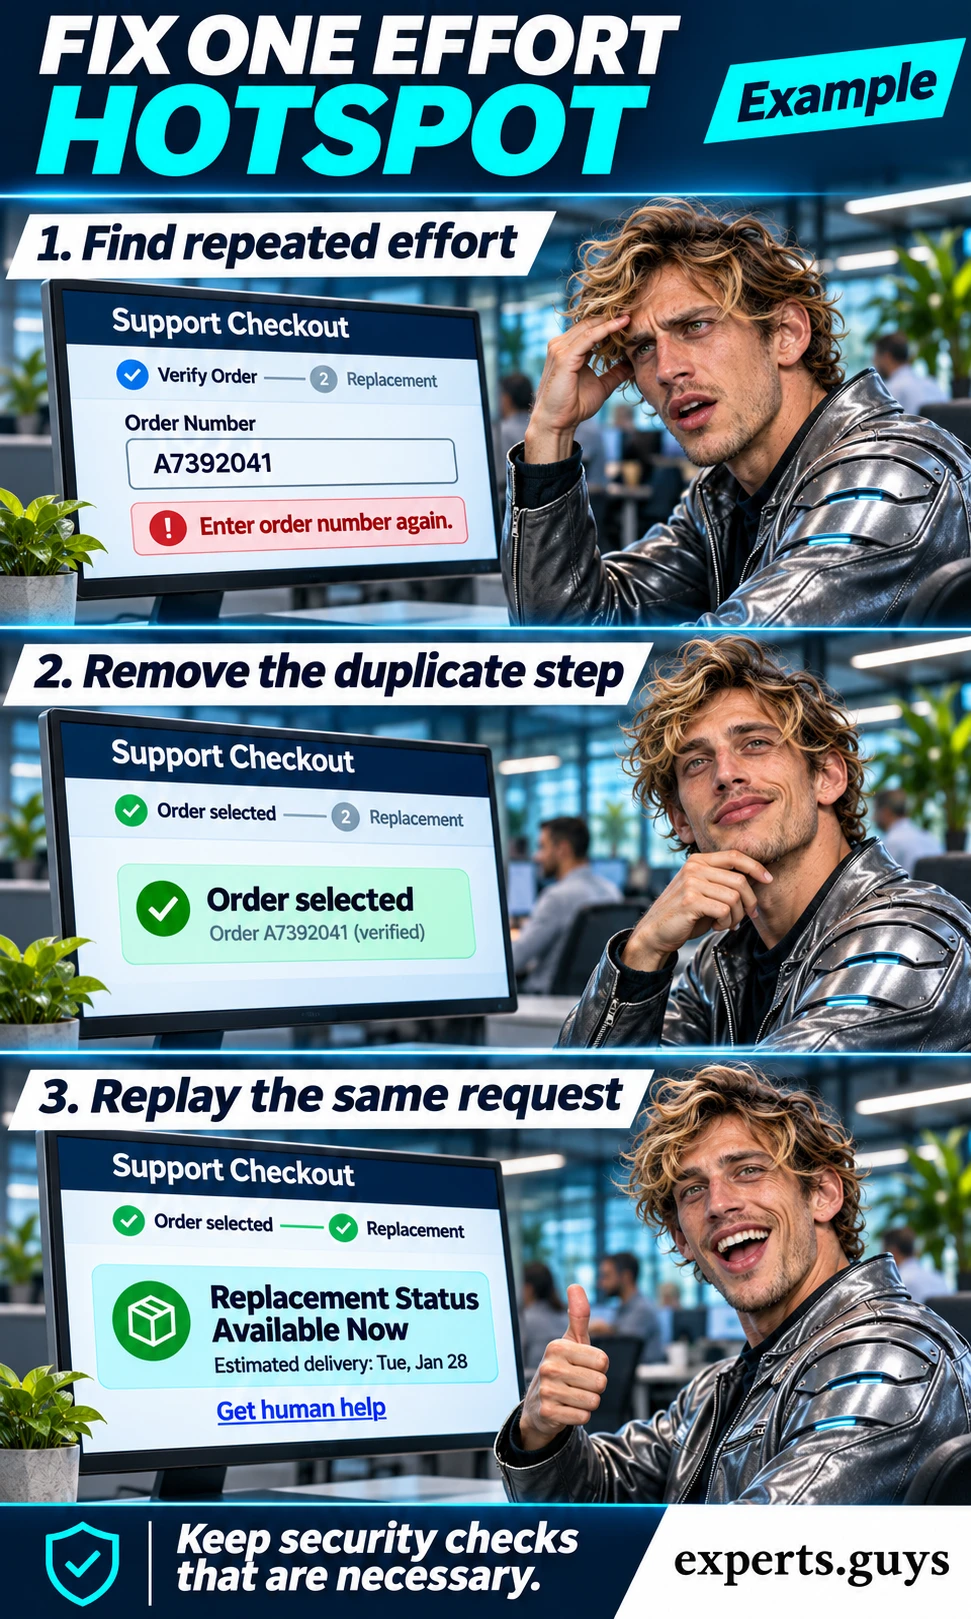
Return to the replay and select one avoidable step. For example, if an already verified order number is requested again after the customer changes from the chatbot to a status view, preserve the permitted context instead of asking for duplicate entry. Keep identity checks that are genuinely required; reducing friction must not expose another customer’s records.
Apply the change in a controlled test route, then replay the same request and an exception such as an expired session. The improvement passes when the ordinary case avoids unnecessary repetition and the exception still asks for the information or authentication it needs. If changing the integration is not yet possible, make the required next step explicit and remove misleading assurances that the context will be carried over.
After the change reaches its approved audience, compare the same task and observation window. Inspect returning cases as well as ratings. If effort falls but incorrect answers increase, the change needs revision; if the score is flat but a specific repeated step disappears, you have a useful operational improvement without evidence of a satisfaction increase yet.
Use the Customer Satisfaction Evidence Check
The tool below calculates four descriptive rates from your existing aggregate counts and highlights conflicting signals. It does not predict satisfaction, test statistical significance or decide whether an AI system is ready for deployment. Use the same cohort definitions as the worked example, and keep names, transcripts and account details out of the inputs.
- Enter the baseline and comparison counts: eligible cases, survey invitations, valid responses, satisfied responses and repeat-contact cases.
- Confirm comparable case types, survey rules and complete follow-up windows only when you have checked them. Leave the box unchecked if you are unsure.
- Select Show my next step. Read the CSAT change together with participation, invitation coverage and repeat contact.
- Use Open A4 action card if you need a compact comparison for a team discussion. Reset clears the fields; reloading the page also discards them.
Did service actually improve?
Compare satisfaction with who answered and who came back.
Use aggregate counts only. No customer data is sent or saved.
Load the example to see the mixed result described above: CSAT rises from 80% to 90%, participation falls from 20% to 10%, and repeat contact rises from 10% to 18%. The useful next step is to replay the returning cases and inspect the promised outcome, not to declare that customers are happier across the whole service.
For the wider review of how staff and automated assistance share work, use the separate AI-assisted human-agent assessment article. Keep this page’s decision narrower: did the customer’s task become easier and more dependable, and do the observed rates support that interpretation?
Frequently asked questions
Can a small business improve satisfaction without a chatbot?
Yes. AI can help staff retrieve an approved answer, understand an incoming request or find recurring complaint themes without becoming a customer-facing bot. A simpler search tool or clearer help page may solve the same problem with less maintenance. Choose the intervention that removes the actual friction.
Is customer satisfaction the same as loyalty?
No. Satisfaction describes an evaluation of an experience, while loyalty concerns an ongoing relationship or behavior. A satisfied customer may still leave because of price, availability or a changing need. Do not describe a higher service rating as proof of retention or revenue growth.
Should AI infer a satisfaction score when customers do not answer?
An estimate can support a separately labeled analysis if it is validated for the population and task, but it should not be inserted into the observed CSAT numerator or denominator. Keep predicted sentiment or satisfaction distinct from actual customer feedback, and report its uncertainty.
What if a necessary policy produces an unhappy customer?
An accurate refusal can still disappoint someone. Separate the decision itself from how the service explained it: was the reason clear, was the relevant policy applied correctly, and was an available review route accessible? Improving communication does not mean promising an exception the business cannot grant.
Is there one good CSAT target for every business?
No single target fits every survey design, task or customer population. Compare a stable definition within a meaningful service context and inspect the consequences behind the score. A high result from a narrow group should not hide unresolved problems elsewhere.
Action checklist
- Choose one customer task and replay it through to the real outcome.
- Repair one avoidable effort or promise mismatch while retaining necessary controls.
- Compare matching cases, stable survey rules and complete follow-up windows.
- Read satisfaction, participation and repeat contact together before expanding the change.