Why Enterprise AI Failures Often Look Similar
Many organizations assume enterprise AI failures are unique.
A healthcare provider may experience regulatory issues. A bank may encounter model governance concerns. A retailer may struggle with customer experience degradation. A manufacturer may face operational disruptions. At first glance, these events appear unrelated because they occur in different industries and involve different technologies.
However, when organizations investigate deeply enough, a different picture begins to emerge.
The visible symptoms may vary.
The underlying failure mechanisms often remain remarkably similar.
This is one reason enterprise AI failures continue repeating despite billions of dollars in technology investment and years of accumulated industry experience. Organizations frequently focus on the surface characteristics of failure while overlooking the structural conditions that make failure likely.
The result is a recurring cycle where different companies experience different consequences driven by similar governance weaknesses.
Understanding these recurring patterns is essential because enterprise AI failure is rarely random.
Most failures follow identifiable pathways long before significant damage becomes visible.
Why Most AI Failures Begin Before Deployment
Many discussions about AI risk focus on what happens after deployment.
This perspective can be misleading.
Most enterprise AI failures begin much earlier.
Long before a model is deployed, organizations make decisions regarding:
- ownership
- governance
- accountability
- oversight
- objectives
- risk acceptance
Enterprise AI Failure Pattern Diagnostic Engine
Identify whether your organization is showing early signs of governance failure, accountability gaps, ROI measurement weakness, oversight erosion, deployment scale shock or AI risk accumulation.
These decisions establish the conditions under which future AI systems will operate.
If accountability is unclear before deployment, accountability usually remains unclear afterward.
If governance structures are weak before deployment, governance rarely becomes stronger automatically.
If leadership responsibilities are undefined during implementation, responsibility often becomes fragmented during operation.
Technology may expose these weaknesses.
Technology rarely creates them.
This distinction helps explain why organizations with completely different AI systems can experience strikingly similar outcomes.
Why Technical Excellence Does Not Prevent Failure
One of the most persistent misconceptions surrounding enterprise AI is the belief that better technology automatically produces better outcomes.
Technology quality matters.
It simply does not determine every outcome.
An enterprise can possess:
- highly accurate models
- advanced infrastructure
- sophisticated vendors
- experienced technical teams
and still experience failure.
This occurs because enterprise outcomes depend upon more than technical performance.
Organizations must also manage:
- governance quality
- accountability clarity
- decision ownership
- operational controls
- escalation mechanisms
When these elements remain weak, technical excellence often becomes insufficient protection against organizational failure.
Many enterprise AI failures occur despite strong technical performance rather than because of poor technical performance.
Why Organizations Misdiagnose AI Failure
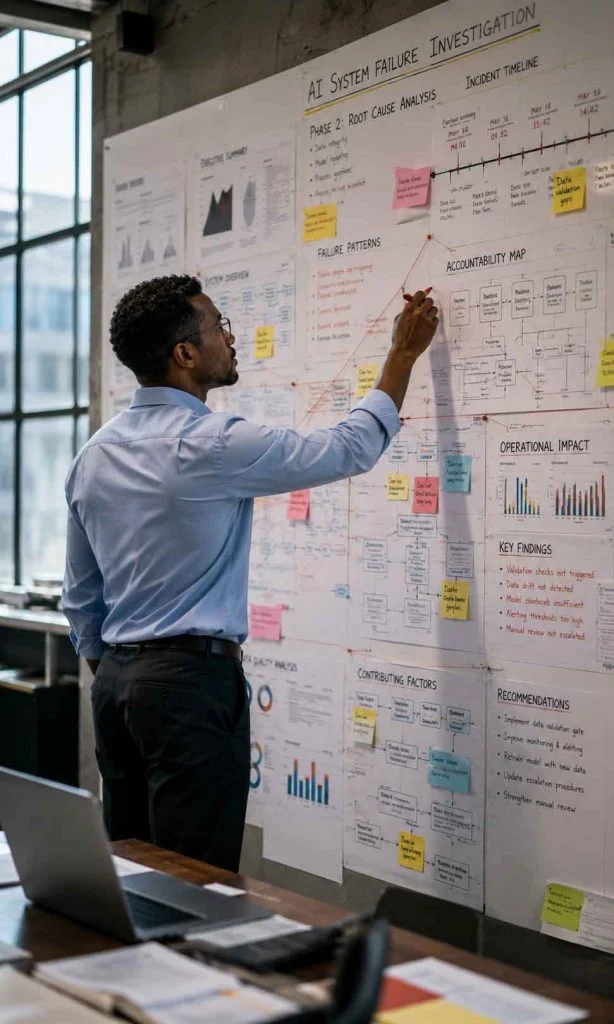
When enterprise AI initiatives fail, most organizations immediately search for a visible explanation.
The search often begins with technology.
Leaders review models. Teams examine data quality. Vendors are questioned. Technical performance metrics are scrutinized. New tools are evaluated. Additional investments are proposed.
These actions appear logical because the visible failure usually emerges through a technical system.
However, the visible point of failure and the actual source of failure are often very different.
This distinction explains why many organizations repeatedly experience similar AI challenges despite replacing platforms, changing vendors, retraining models, or increasing technology spending.
The organization addresses what failed.
It does not address why failure became possible.
Why Technical Blame Is Usually The First Reaction
Technology is tangible.
Governance is not.
When a customer-facing AI system produces poor outcomes, stakeholders naturally focus on the system that produced the outcome. The model becomes the center of attention because it is visible, measurable, and easy to discuss.
Questions quickly emerge:
- Was the model accurate?
- Was the training data sufficient?
- Was the algorithm flawed?
- Was the vendor responsible?
- Was the implementation incomplete?
These questions matter.
Yet they frequently represent only a small portion of the overall problem.
In many enterprise environments, the technical system simply exposes organizational weaknesses that already existed before deployment began.
Technology becomes the messenger.
The organization mistakenly treats it as the cause.
Why Vendor Blame Creates A False Sense Of Resolution
Enterprise AI projects often involve:
- software vendors
- implementation partners
- consulting firms
- cloud providers
- external platforms
When results disappoint, organizations frequently shift attention toward external providers.
This reaction is understandable.
External parties are easy to identify.
Contracts exist.
Deliverables exist.
Service agreements exist.
However, vendor replacement rarely resolves structural governance problems.
An organization that lacks:
- accountability ownership
- escalation procedures
- oversight mechanisms
- executive sponsorship
can experience similar failures regardless of which vendor supplies the technology.
This is one reason enterprise AI failures often survive multiple technology generations.
The platform changes.
The underlying governance structure remains unchanged.
Why Data Problems Often Hide Governance Problems
Poor data quality is one of the most frequently cited causes of AI failure.
Sometimes the diagnosis is accurate.
More often, data quality issues reveal something deeper.
Data governance itself requires:
- ownership
- accountability
- review processes
- quality controls
- escalation procedures
When these elements are weak, data quality naturally deteriorates over time.
Organizations often describe the situation as a data problem.
In reality, the data problem may be a symptom of a governance problem.
The distinction matters because improving data quality without improving governance frequently produces only temporary improvement.
Eventually the same structural weaknesses reappear.
The organization solves the symptom.
The mechanism survives.
Why AI Failure Frequently Begins As A Leadership Failure
Many investigations ultimately reveal weaknesses in executive AI accountability long before technical problems become visible.
Many executives view AI deployment as a technology initiative supported by leadership.
Mature organizations eventually recognize a different reality.
AI deployment is often a leadership initiative supported by technology.
The distinction is subtle but important.
Technology teams can deploy systems.
Technology teams cannot independently define:
- organizational priorities
- risk tolerance
- accountability structures
- governance standards
- escalation authority
Those responsibilities belong to leadership.
When these leadership responsibilities remain unclear, technology teams frequently inherit decisions they were never designed to make.
The resulting failures often appear technical even though they originate from leadership gaps.
Why Organizations Mistake Symptoms For Causes
A useful way to understand enterprise AI failure is to separate symptoms from causes.
Symptoms are visible.
Causes are structural.
For example:
| Visible Symptom | Possible Structural Cause |
|---|---|
| Poor AI outputs | Weak governance oversight |
| Compliance concerns | Unclear accountability |
| ROI disappointment | Incorrect success metrics |
| Operational disruption | Inadequate deployment controls |
| Escalation failure | Undefined ownership structure |
Organizations naturally focus on symptoms because symptoms create immediate pain.
However, lasting improvement usually requires understanding the structural conditions that allowed those symptoms to emerge.
This is where many enterprises struggle.
They become experts at fixing incidents.
They never become experts at preventing recurring failure mechanisms.
Why Failure Investigations Often Stop Too Early
After a significant AI-related incident, organizations commonly perform reviews designed to identify lessons learned.
These reviews can be valuable.
However, many investigations stop once an immediate explanation is discovered.
Examples include:
- model error identified
- process failure identified
- data issue identified
- vendor issue identified
While these findings may be accurate, they often represent only one layer of the problem.
A deeper investigation typically asks:
- Why was the issue not detected earlier?
- Why did escalation not occur?
- Why was accountability unclear?
- Why were controls insufficient?
- Why did governance fail to intervene?
These questions move beyond technical analysis and into organizational analysis.
That is where recurring failure patterns usually become visible.
The Seven Enterprise AI Failure Patterns
When enterprise AI failures are examined across industries, technologies, and use cases, recurring patterns begin to emerge.
These patterns are not random.
They represent structural weaknesses that repeatedly appear regardless of whether an organization operates in banking, healthcare, manufacturing, retail, logistics, insurance, telecommunications, or professional services.
The specific technology may change.
The organizational behavior often remains remarkably consistent.
Understanding these patterns is valuable because they frequently become visible long before major incidents occur.
Organizations that recognize the patterns early can often identify risks before consequences become significant.
Organizations that ignore them frequently discover the pattern only after failure becomes expensive.
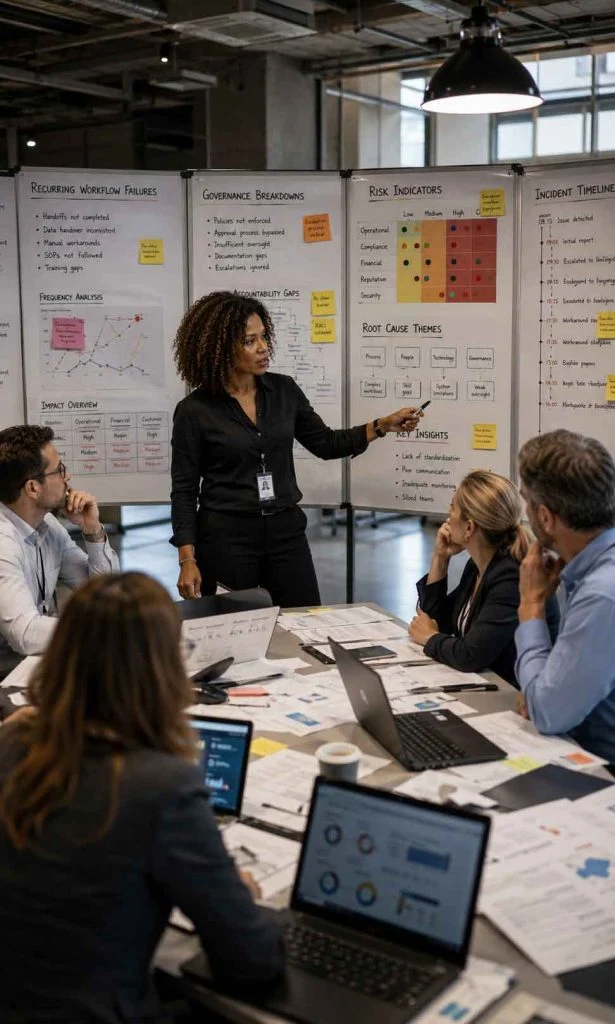
Pattern 1: Governance Vacuum
The most common enterprise AI failure pattern begins with the absence of governance.
A governance vacuum exists when organizations deploy AI without clearly defining:
- ownership
- oversight
- approval authority
- escalation responsibility
- risk acceptance
During early deployment stages, this absence may appear harmless.
Pilot projects often operate within small environments where informal communication compensates for missing governance structures.
As deployment expands, informal arrangements begin to break down.
Questions emerge:
- Who approves expansion?
- Who reviews outcomes?
- Who owns the risk?
- Who intervenes when concerns arise?
Without governance, different departments frequently assume someone else is responsible.
This creates an environment where accountability becomes fragmented and risks accumulate unnoticed.
Many enterprise AI failures begin here.
Pattern 2: Executive Accountability Gaps
Weak executive AI accountability frequently transforms manageable operational issues into enterprise-wide governance failures.
Governance and accountability are closely related but not identical.
Governance defines structures.
Accountability defines ownership.
Organizations often create governance processes without establishing clear accountability.
This creates situations where:
- reviews occur
- meetings occur
- reports exist
- committees exist
yet responsibility remains unclear.
When accountability gaps emerge, organizations struggle to answer a simple question:
Who owns the outcome?
If the answer requires multiple meetings and conflicting interpretations, accountability may already be insufficient.
These gaps often remain invisible during success.
They become highly visible during failure.
Pattern 3: ROI Measurement Failure
Many organizations deploy AI expecting measurable returns.
The challenge is that measuring AI success becomes increasingly difficult as deployments expand.
Early-stage projects often focus on:
- productivity gains
- automation savings
- operational efficiency
These metrics are useful.
However, mature deployments influence:
- decision quality
- risk exposure
- customer outcomes
- compliance performance
- organizational resilience
These outcomes are far more difficult to measure.
As a result, organizations frequently rely on simplified metrics that fail to capture the full impact of deployment.
Leadership teams may believe AI is succeeding because dashboards appear positive.
Meanwhile, hidden costs, governance weaknesses, and operational risks continue accumulating.
This creates a dangerous disconnect between reported success and actual performance.
Pattern 4: Hidden Cost Expansion
One of the most underestimated AI failure mechanisms involves cost growth.
Initial business cases often emphasize:
- licensing costs
- implementation costs
- infrastructure costs
Over time, additional expenses emerge:
- monitoring
- governance
- compliance
- retraining
- oversight
- auditing
- incident management
These costs frequently expand faster than anticipated.
The result is not necessarily financial failure.
The result is expectation failure.
Organizations compare real operating costs against unrealistic projections and conclude that AI underperformed.
In reality, the deployment may have succeeded while the original assumptions failed.
Many organizations underestimate the hidden costs of AI adoption until governance, monitoring, and oversight expenses begin expanding beyond original projections.
Pattern 5: Oversight Erosion
Most organizations begin AI deployment with strong oversight.
New initiatives receive attention.
Leadership participates.
Governance reviews occur.
Performance is monitored.
As deployment matures, attention often declines.
This creates oversight erosion.
Oversight erosion occurs when:
- review frequency decreases
- executive attention shifts
- governance participation declines
- monitoring becomes inconsistent
The system continues operating.
However, organizational visibility gradually weakens.
Many significant enterprise AI failures occur after oversight declines rather than during initial deployment.
Pattern 6: Deployment Scale Shock
AI systems that function effectively in limited environments may behave differently at enterprise scale.
Scale introduces:
- additional users
- additional workflows
- additional dependencies
- additional risk exposure
The organization may underestimate how complexity changes operational behavior.
A system that performs well for one department may create unexpected consequences when expanded across multiple departments.
This phenomenon is known as deployment scale shock.
The failure is not necessarily technological.
The organization simply encounters complexity it did not anticipate.
Pattern 7: Risk Accumulation
These conditions help explain why AI risk builds quietly before enterprise failures even when operational indicators appear stable.
Perhaps the most important failure pattern involves gradual risk accumulation.
Risk accumulation rarely creates immediate warning signs.
Instead, small issues develop over time:
- accountability becomes unclear
- oversight weakens
- governance participation declines
- monitoring gaps emerge
- escalation pathways deteriorate
Each individual issue may appear manageable.
Collectively, they create an increasingly fragile environment.
Eventually a triggering event exposes the accumulated weaknesses.
Observers often view the resulting incident as sudden.
In reality, the underlying conditions may have been developing for months or years.
This is why many enterprise AI failures appear surprising despite leaving visible signals long beforehand.
Why Failure Repeats Across Industries
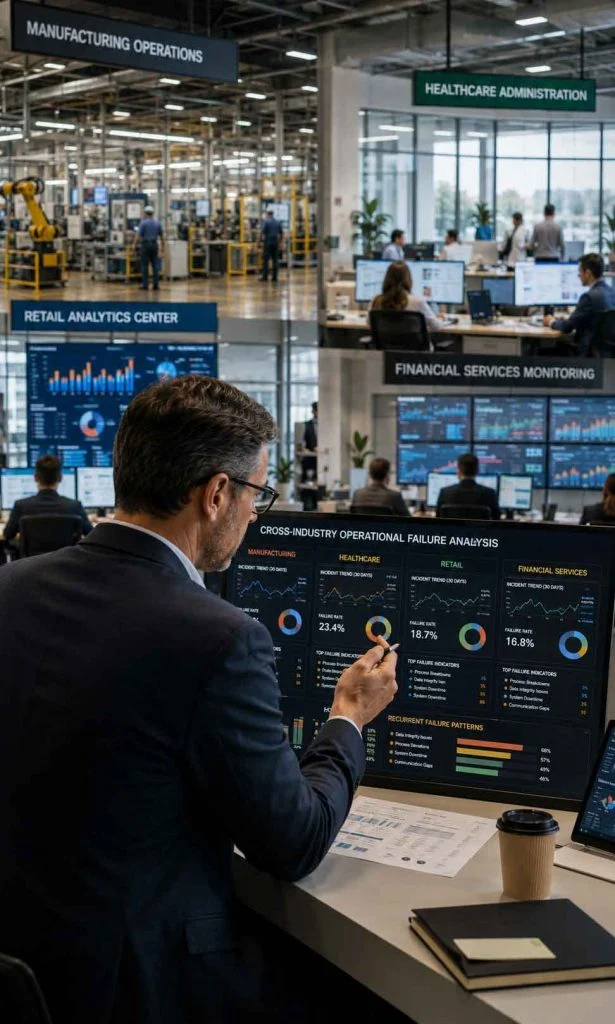
One of the most revealing aspects of enterprise AI failure is that similar patterns appear across industries that have very little in common operationally.
A hospital and a manufacturing plant operate differently.
A bank and a retailer serve different customers.
A government agency and a logistics company face different regulatory environments.
Despite these differences, investigations often uncover remarkably similar governance weaknesses, accountability gaps, oversight failures, and leadership blind spots.
The industry changes.
The failure mechanism often does not.
This is why studying enterprise AI failure patterns across industries provides valuable insight. The goal is not to understand a particular technology problem. The goal is to understand recurring organizational behavior.
Once the organizational behavior becomes visible, many future failures become easier to recognize.
Why Banking AI Failures Often Begin With Governance Complexity
Financial institutions typically operate within highly regulated environments.
Governance structures already exist for:
- financial risk
- operational risk
- compliance risk
- cybersecurity risk
At first glance, this should reduce AI-related failures.
In practice, the opposite sometimes occurs.
The challenge is complexity.
Banks often deploy AI into environments containing:
- multiple approval layers
- multiple oversight functions
- multiple reporting structures
- multiple risk frameworks
As AI systems interact with these structures, accountability can become fragmented.
Different teams may assume governance exists because multiple controls exist.
However, control abundance does not always create accountability clarity.
Many banking AI failures originate from unclear ownership inside highly structured environments rather than from an absence of controls.
Why Healthcare AI Failures Often Begin With Responsibility Confusion
Healthcare organizations frequently adopt AI to improve:
- operational efficiency
- patient workflows
- resource allocation
- administrative processes
These objectives appear straightforward.
The challenge emerges when decision influence becomes distributed across multiple stakeholders.
For example:
- clinicians
- administrators
- compliance teams
- technology teams
- external vendors
Each group may interact with AI-supported processes differently.
As responsibilities become distributed, accountability can become increasingly difficult to trace.
Healthcare organizations often discover that the challenge is not whether AI recommendations were available.
The challenge is determining who ultimately owns decisions influenced by those recommendations.
This creates a recurring pattern where responsibility confusion becomes a larger problem than technical performance.
Why Retail AI Failures Often Begin With Scale
Retail organizations frequently experience AI success quickly.
Customer engagement improves.
Personalization improves.
Operational efficiency improves.
These successes encourage expansion.
Additional use cases are introduced.
More customer interactions become AI-supported.
More decisions become automated.
The challenge is not initial deployment.
The challenge is scale.
As scale expands, governance requirements expand as well.
Organizations sometimes assume successful pilots automatically translate into successful enterprise deployment.
This assumption creates deployment scale shock.
The same mechanism appears repeatedly across retail environments regardless of the specific technology involved.
Why Manufacturing AI Failures Often Begin With Operational Dependency
Manufacturing organizations frequently deploy AI to support:
- production planning
- maintenance scheduling
- quality monitoring
- operational forecasting
Over time, operational teams may become increasingly dependent on AI-supported outputs.
Dependency itself is not necessarily problematic.
The challenge emerges when dependency grows faster than oversight.
Organizations begin trusting outputs because historical performance appears reliable.
Review intensity declines.
Monitoring declines.
Escalation readiness declines.
The system continues functioning until an unexpected event reveals weaknesses that were previously hidden.
This pattern demonstrates how operational dependency can gradually reduce organizational visibility.
Why Government AI Failures Often Begin With Accountability Diffusion
Government organizations face unique challenges involving:
- public trust
- transparency expectations
- policy obligations
- stakeholder scrutiny
AI deployment often involves multiple departments, committees, and oversight functions.
While these structures provide important safeguards, they can also create accountability diffusion.
Accountability diffusion occurs when many stakeholders participate while ownership remains unclear.
Everyone contributes.
Nobody fully owns the outcome.
This environment can make decision-making slower while simultaneously making accountability harder to identify.
The result is a recurring governance challenge rather than a recurring technology challenge.
Why The Industry Matters Less Than The Organizational Structure
Regardless of industry, recurring governance weaknesses often transform manageable concerns into broader AI business risk exposure.
The examples above highlight an important observation.
Banking failures look different from healthcare failures.
Healthcare failures look different from retail failures.
Retail failures look different from manufacturing failures.
Yet when investigators move beyond visible symptoms, similar organizational conditions often appear:
- unclear accountability
- weak governance
- insufficient oversight
- fragmented ownership
- delayed escalation
- leadership visibility gaps
These conditions are not industry-specific.
They are organizational.
This is why enterprise AI failure patterns repeat across industries despite differences in products, services, customers, regulations, and technology environments.
Organizations frequently believe they face unique problems.
The underlying mechanisms are often surprisingly familiar.
Why Similar Mechanisms Produce Different Symptoms
A useful analogy involves structural engineering.
Two buildings may experience different visible damage.
One develops cracks.
Another develops foundation movement.
A third develops water intrusion.
The symptoms differ.
The underlying structural weakness may be similar.
Enterprise AI behaves in much the same way.
Different organizations experience:
- different incidents
- different disruptions
- different financial outcomes
- different compliance concerns
However, recurring governance weaknesses often remain consistent beneath the surface.
This insight is valuable because it shifts attention away from isolated incidents and toward recurring organizational mechanisms.
Organizations that understand mechanisms typically respond more effectively than organizations focused only on symptoms.
How Mature Organizations Interrupt Failure Cycles
One of the most important observations in enterprise AI governance is that mature organizations rarely eliminate every risk.
Instead, they become better at identifying risks before those risks become incidents.
This distinction matters because many organizations pursue an unrealistic objective.
They attempt to create perfect deployments.
Mature organizations pursue a different objective.
They create environments capable of detecting, understanding, and responding to emerging problems before those problems become expensive.
This shift in thinking often separates organizations that repeatedly experience AI-related disruption from organizations that sustain long-term AI adoption.
The goal is not perfection.
The goal is organizational resilience.
Why Early Warning Systems Matter More Than Incident Response
Many enterprises invest heavily in incident response capabilities.
While response capabilities remain important, mature organizations increasingly recognize that prevention begins with visibility.
An effective early warning system identifies conditions that frequently precede failure.
Examples include:
- declining governance participation
- inconsistent review processes
- ownership confusion
- escalation delays
- monitoring gaps
- increasing exception rates
None of these indicators necessarily represent failure.
However, they often indicate that the environment supporting AI deployment is becoming less stable.
Organizations that monitor these signals can often intervene long before visible disruption occurs.
Organizations that ignore them frequently discover problems only after consequences become significant.
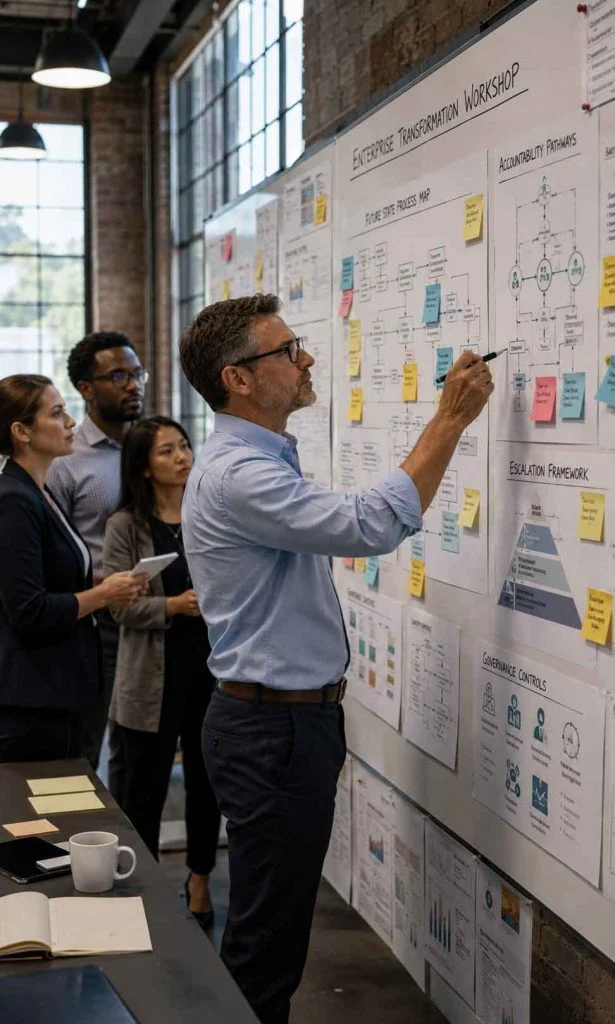
Why Accountability Mapping Reduces Organizational Blind Spots
Many enterprises document technical systems in extraordinary detail.
Surprisingly, they often document accountability with far less precision.
Accountability mapping addresses this problem by clearly identifying:
- who owns deployment decisions
- who owns business outcomes
- who owns governance reviews
- who owns escalation authority
- who owns intervention responsibility
The objective is not administrative complexity.
The objective is visibility.
When accountability pathways become visible, leadership teams can quickly identify gaps that might otherwise remain hidden.
Organizations frequently discover that multiple people believe ownership exists while nobody actually possesses clear responsibility.
Accountability mapping transforms assumptions into documented structures.
That alone can significantly reduce governance risk.
Why Governance Maturity Changes Failure Outcomes
Governance maturity does not eliminate mistakes.
It changes how organizations respond when mistakes occur.
Low-maturity environments often experience:
- delayed detection
- fragmented communication
- unclear ownership
- inconsistent intervention
High-maturity environments typically demonstrate:
- faster detection
- clearer accountability
- structured escalation
- coordinated response
The difference is not necessarily technology quality.
The difference is organizational readiness.
This is one reason governance maturity often predicts long-term deployment success more accurately than technical sophistication alone.
Organizations with average technology and strong governance frequently outperform organizations with advanced technology and weak governance.
Why Escalation Frameworks Create Organizational Stability
Many AI failures become expensive because concerns remain unresolved for too long.
An employee notices an issue.
A manager observes unexpected outcomes.
A compliance concern emerges.
A customer experience problem appears.
The question becomes:
What happens next?
Organizations with strong escalation frameworks provide clear answers.
They establish:
- reporting channels
- review responsibilities
- decision authority
- intervention thresholds
- communication pathways
These mechanisms allow concerns to move rapidly toward individuals capable of taking action.
Without escalation structures, organizations often spend valuable time determining who should respond rather than actually responding.
Why Continuous Oversight Is More Effective Than Periodic Reviews
Building sustainable AI oversight structures often determines whether governance quality strengthens or weakens as deployments mature.
Many organizations rely on periodic governance reviews.
Quarterly reviews.
Annual reviews.
Project milestone reviews.
These activities remain useful.
However, mature organizations increasingly recognize that enterprise AI operates continuously.
Oversight therefore benefits from continuous visibility rather than isolated checkpoints.
Continuous oversight focuses on:
- performance monitoring
- governance participation
- accountability adherence
- exception tracking
- operational indicators
The objective is not constant intervention.
The objective is maintaining awareness.
Organizations that maintain visibility generally identify emerging issues earlier than organizations that rely exclusively on scheduled reviews.
Why Mature Organizations Focus On Failure Signals Instead Of Failure Events
Less mature organizations frequently concentrate on incidents.
Mature organizations concentrate on signals.
An incident represents a visible outcome.
A signal represents a developing condition.
For example:
| Failure Event | Earlier Signal |
|---|---|
| Governance breakdown | Declining governance participation |
| Accountability confusion | Ownership ambiguity |
| Escalation failure | Delayed issue reporting |
| Compliance concern | Increasing exception frequency |
| Operational disruption | Visibility gaps |
The ability to recognize signals before events occur often becomes a defining characteristic of organizational maturity.
Organizations that monitor signals generally spend less time reacting to crises and more time preventing them.
Why Successful Organizations Treat Failure Patterns As Leading Indicators
One of the most important lessons from enterprise AI adoption is that failure patterns themselves become valuable data.
Organizations often treat failures as isolated events.
Mature organizations treat recurring failure mechanisms as leading indicators.
A governance vacuum is not merely a problem.
It is a warning signal.
Accountability gaps are not merely weaknesses.
They are predictors.
Oversight erosion is not merely a governance concern.
It is an indicator of future vulnerability.
This perspective fundamentally changes how organizations evaluate AI risk.
Instead of asking:
What failed?
Mature organizations increasingly ask:
What conditions make failure more likely?
The second question tends to produce more durable answers.
Why Enterprise AI Failure Is Usually Predictable
One of the most persistent myths surrounding enterprise AI is the belief that major failures emerge suddenly.
Organizations often describe significant incidents as unexpected.
Investigations frequently use terms such as:
- unforeseen
- unpredictable
- surprising
- unprecedented
However, when post-incident reviews become sufficiently detailed, a different pattern often emerges.
Many enterprise AI failures produce warning signs long before visible disruption occurs.
The signals exist.
The challenge is that organizations frequently fail to recognize their significance.
Enterprise AI failures rarely emerge from a single mistake. Most develop from organizational conditions that become increasingly fragile over time.
As a result, what appears sudden from the outside often develops gradually on the inside.
This is why mature organizations increasingly focus on predictability rather than reaction.
The objective is not to predict every incident.
The objective is to recognize conditions that make incidents more likely.
Why Warning Signals Frequently Appear Months Before Failure
Enterprise failures rarely begin with catastrophic events.
More commonly, they begin with small changes that appear insignificant when viewed individually.
Examples include:
- governance participation declining
- ownership becoming unclear
- review frequency decreasing
- escalation delays increasing
- monitoring becoming inconsistent
- exception rates gradually rising
None of these indicators automatically produce failure.
The challenge is cumulative impact.
Over time, multiple small weaknesses interact with one another.
The organization continues functioning.
Performance metrics may even remain positive.
Yet the environment becomes increasingly fragile.
When a triggering event eventually occurs, accumulated weaknesses become visible simultaneously.
Observers focus on the trigger.
The actual cause often developed long beforehand.
Why Executive Blind Spots Create Predictable Vulnerabilities
Enterprise leaders rarely ignore risk intentionally.
More often, blind spots emerge because information becomes fragmented.
Different departments possess different perspectives.
Technology teams observe technical indicators.
Operations teams observe workflow indicators.
Compliance teams observe regulatory indicators.
Executives observe strategic indicators.
The challenge is integration.
When no mechanism exists to combine these perspectives, warning signals remain distributed across the organization.
Each individual team sees part of the picture.
Nobody sees the whole picture.
This fragmentation creates predictable vulnerabilities because risks continue developing while organizational visibility remains incomplete.
Why Success Often Hides Emerging Failure Conditions
An interesting characteristic of enterprise AI is that success can sometimes obscure risk.
Positive performance metrics create confidence.
Confidence encourages expansion.
Expansion increases complexity.
Complexity increases governance requirements.
If governance capabilities do not expand at the same rate, organizational risk begins growing beneath the surface.
This dynamic explains why some enterprises encounter significant challenges shortly after periods of apparent success.
The problem is not that success created failure.
The problem is that success concealed conditions that made future failure more likely.
Why Organizations Ignore Signals They Do Not Measure
Many organizations overlook how misleading AI success metrics can become when governance indicators are excluded from measurement frameworks.
Organizations generally manage what they measure.
This principle applies to AI as much as any other business activity.
Most enterprises measure:
- performance
- efficiency
- productivity
- cost savings
Far fewer measure:
- accountability clarity
- governance participation
- escalation effectiveness
- oversight quality
- ownership consistency
As a result, governance deterioration can remain invisible even while operational metrics appear healthy.
This creates an imbalance where technical indicators receive extensive attention while organizational indicators receive limited attention.
Many recurring AI failures emerge from precisely this imbalance.
Why Future Enterprise AI Risk Will Become More Organizational
As AI capabilities continue advancing, many discussions remain focused on technology.
Organizations naturally ask:
- How accurate are the models?
- How capable are the systems?
- How quickly is technology improving?
These questions remain important.
However, future enterprise AI risk is likely to become increasingly organizational rather than purely technical.
The key challenges may involve:
- governance scalability
- accountability clarity
- oversight sustainability
- decision ownership
- escalation readiness
Technology will continue evolving.
The ability of organizations to govern that technology may become the more important differentiator.
This trend is already visible across many large-scale deployments.
Why Predictability Creates Strategic Advantage
Organizations that understand recurring failure mechanisms gain an important advantage.
They stop treating incidents as isolated events.
Instead, they begin recognizing patterns.
Patterns create predictability.
Predictability improves decision-making.
Improved decision-making strengthens governance.
Stronger governance reduces vulnerability.
This cycle often separates organizations that repeatedly encounter AI-related disruption from organizations that successfully sustain long-term deployment.
The objective is not eliminating uncertainty.
The objective is reducing avoidable uncertainty.
That distinction is critical.
Conclusion
Enterprise AI failures often appear unique because the visible symptoms differ across industries, technologies, and deployment environments.
A closer examination reveals a different reality.
Recurring organizational mechanisms frequently drive recurring enterprise outcomes.
Governance vacuums, accountability gaps, measurement failures, hidden cost expansion, oversight erosion, deployment scale shock, and gradual risk accumulation appear repeatedly across industries because they reflect organizational behavior rather than technological behavior.
This observation helps explain why enterprise AI failures often remain predictable long before they become visible.
Organizations that focus exclusively on technical performance frequently miss important signals.
Organizations that understand recurring failure mechanisms often identify risks earlier, respond more effectively, and sustain AI deployment more successfully over time.
The future of enterprise AI success may depend less on avoiding every mistake and more on recognizing the organizational conditions that make mistakes increasingly likely.
Understanding failure patterns is therefore not simply an exercise in risk management.
It is a foundation for building more resilient AI-enabled organizations.
FAQ
Why do enterprise AI failures repeat across industries?
Many enterprise AI failures originate from recurring organizational weaknesses such as governance gaps, accountability confusion, oversight erosion, and measurement problems rather than industry-specific technology issues.
What is the most common enterprise AI failure pattern?
Governance vacuums are among the most common failure patterns because unclear ownership, oversight, and escalation responsibilities allow risks to accumulate over time.
Can successful AI projects still fail later?
Yes. Many organizations experience deployment scale shock, oversight erosion, and accountability challenges after early success expands AI into additional business functions.
Why do organizations misdiagnose AI failure?
Organizations often focus on technical symptoms such as model accuracy or data quality while overlooking governance, accountability, leadership, and oversight mechanisms that create the underlying conditions for failure.
Are enterprise AI failures predictable?
Many enterprise AI failures generate warning signals months before visible disruption occurs. Governance deterioration, ownership confusion, oversight gaps, and escalation weaknesses often appear before major incidents.